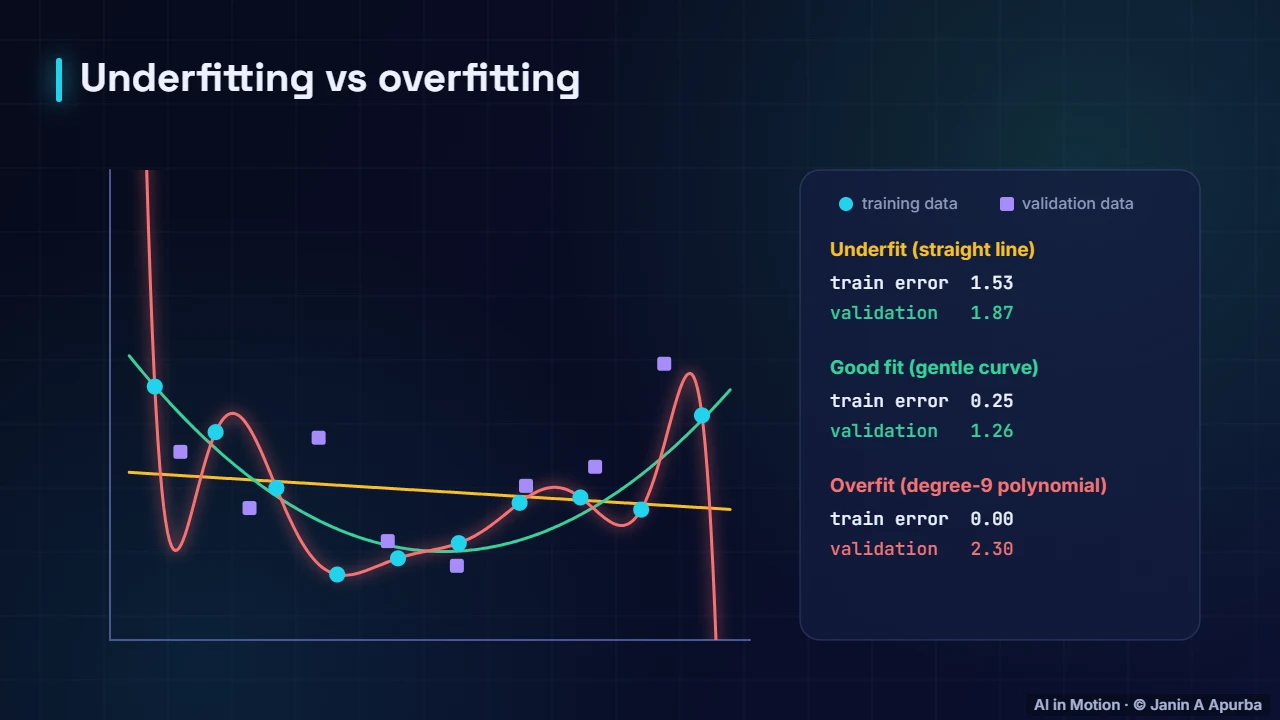
Overfitting, Underfitting and Bias–Variance
Too simple, just right, too complex: see three models on the same data and why validation error — not training error — tells the truth.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. The goal of machine learning is not to fit the training data. It is to do well on new data. Two opposite failures get in the way.
Three models. The same data, three models. A straight line underfits: training error 1.53. A gentle curve fits well: 0.25. A degree nine polynomial passes through every point: training error zero. But on new validation points, the curve wins with 1.26, while the overfit model is worst at 2.30.
Bias and variance. Think of darts. High bias means aiming off-centre, like a model that is too simple. High variance means throws scattered everywhere, like a model that changes wildly with small changes in data. We want low bias and low variance.
Learning curves. Learning curves reveal overfitting during training. Training loss keeps falling, but validation loss stops improving and starts rising. The widening gap means the model is memorising. Early stopping keeps the model from the best point.
Fixes. To fix underfitting, use a more flexible model, better features, or train longer. To fix overfitting, get more data, simplify or regularise the model, and use tricks like early stopping, dropout and data augmentation.
Recap. To recap. Underfitting is too simple. Overfitting memorises. Always judge by validation error, and aim for the balance between bias and variance.