Train/Test Splits and Cross-Validation
Why data is split into training, validation and test sets — and how k-fold cross-validation gives a more reliable score.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. If students see the exam questions in advance, their scores mean nothing. Models are the same. To know how good a model really is, we must test it on data it has never seen.
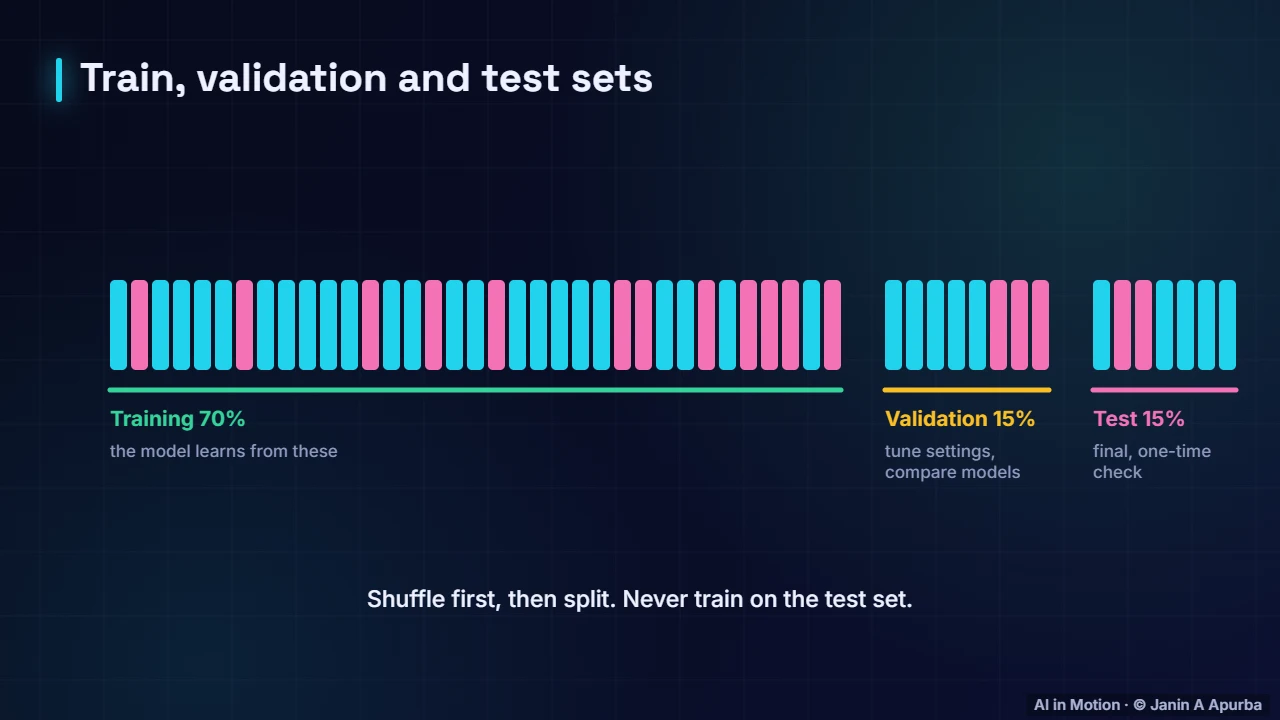
Splitting the data. First shuffle the data so every part is representative. Then split it. Around seventy percent for training, fifteen percent for validation to tune settings, and fifteen percent for a final test that we look at only once.
Roles. The model learns from the training set. We use the validation set to choose settings and compare models. The test set gives one final honest estimate. If you keep tuning on the test set, it stops being honest.
Cross-validation. With small datasets, one split can be lucky or unlucky. Five-fold cross-validation splits the data into five parts. Each round trains on four and validates on the fifth, until every part has been the validation set once. Here the five example scores average 0.848.
Data leakage. Beware of data leakage: when information from the test data sneaks into training. Duplicates, preprocessing before splitting, features that secretly contain the answer, or shuffling time series. Leakage makes models look brilliant, then fail in reality.
Recap. To recap. Shuffle and split. Tune on validation and test only once. Use cross-validation for small data. And guard carefully against leakage.