Linear Classifiers: Logistic Regression and the Perceptron
Draw a line that separates two classes. Watch logistic regression learn a probabilistic boundary and the perceptron nudge its line towards mistakes.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. Classification means predicting a category: spam or not, pass or fail. The simplest classifiers separate the classes with a straight line.
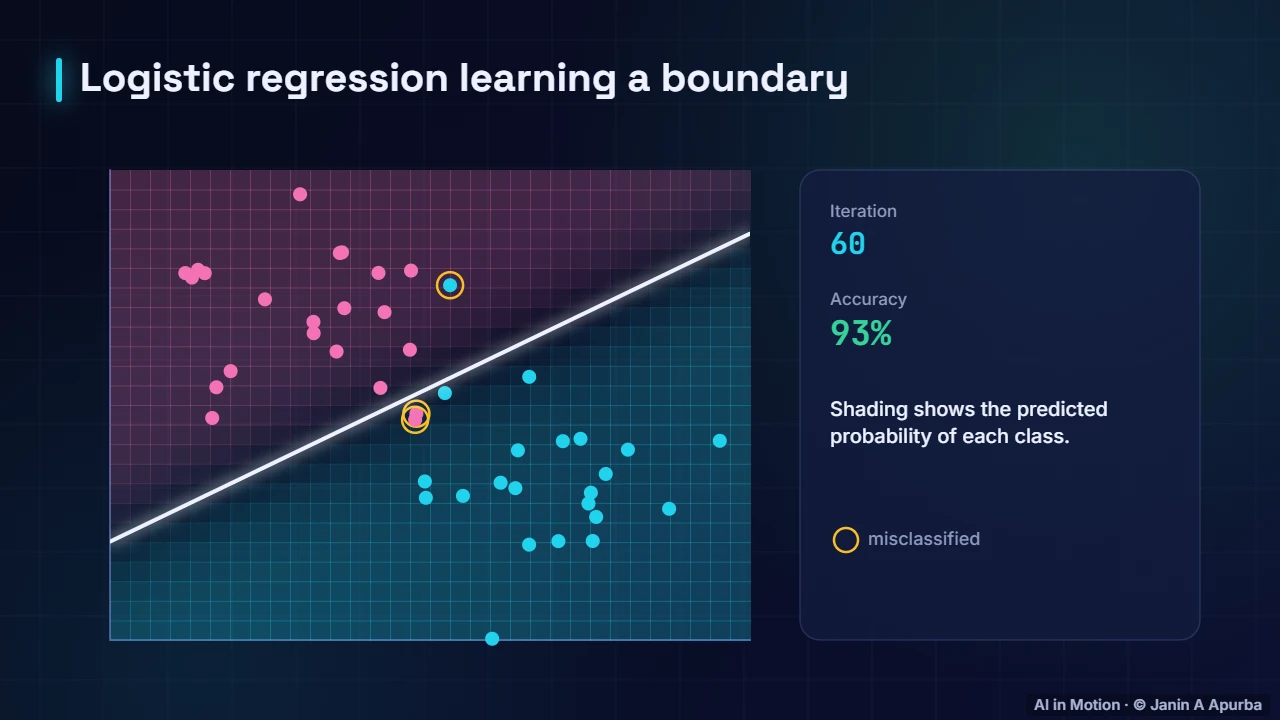
Logistic regression. Logistic regression learns a boundary and a probability for every point. The background shading shows how confident it is. Watch the boundary move as training runs. Accuracy climbs from 59 percent to 93 percent, with a few overlapping points still misclassified.
The sigmoid. The model computes a linear score, like linear regression, and passes it through the sigmoid, which squeezes any number into a probability between zero and one. Above one half, we predict the positive class.
The perceptron. The perceptron, from 1958, is even simpler. It looks at a training point. If the point is on the wrong side, it nudges the line towards it. If it is correct, it does nothing. Repeat, and the line settles into a good position.
Comparison. Logistic regression gives probabilities and trains smoothly. The perceptron only outputs a class and only learns from mistakes. But it is historically important: it is the ancestor of every neural network.
Recap. To recap. Linear classifiers draw a straight boundary. Logistic regression outputs probabilities. The perceptron learns from mistakes. And neither can handle problems that need a curved boundary, which is where more powerful models come in.