k-Nearest Neighbours: Learning by Similarity
Classify a new point by asking its closest neighbours to vote. Simple, intuitive and a great first classifier.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. If you want to guess whether you will like a film, you might ask friends with similar taste. The k nearest neighbours algorithm works exactly like that.
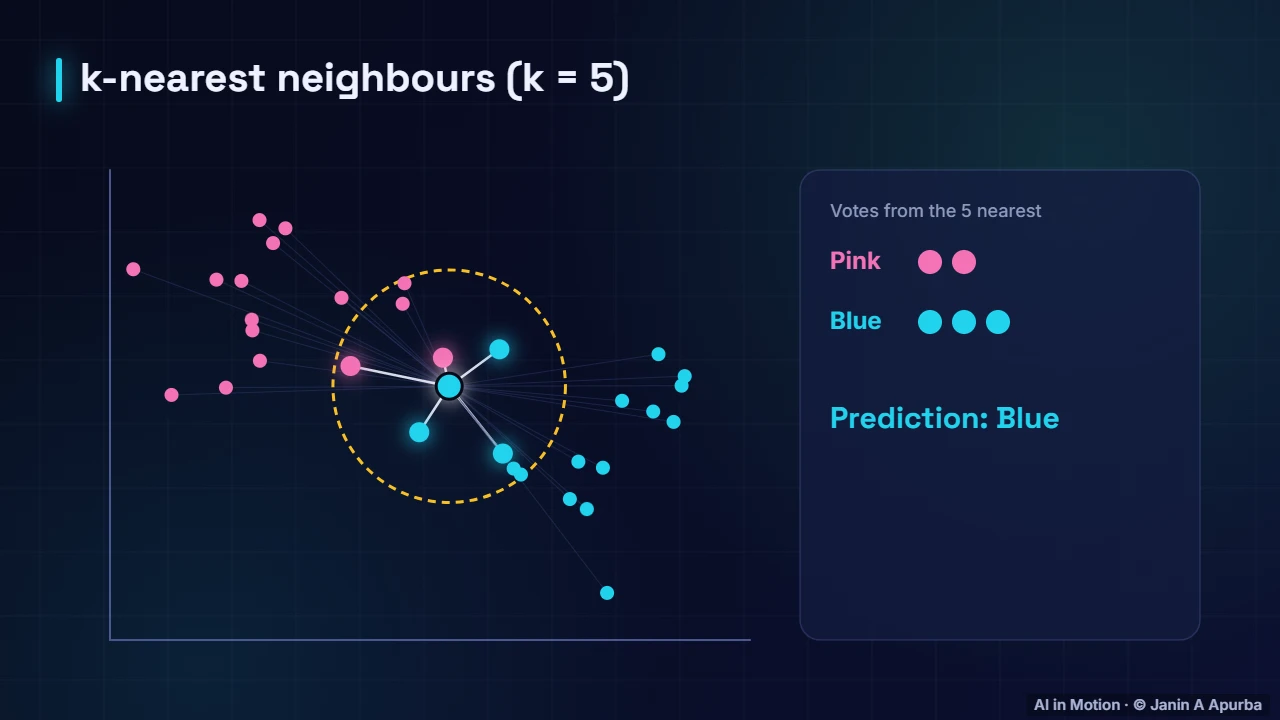
How k-NN classifies. Here are labelled pink and blue points. A new point arrives with no label. We measure its distance to every example, find the five nearest, and let them vote. Three are blue and two are pink, so the new point is classified as blue.
Changing k. With k equals three, the vote is two blue to one pink, still blue. Small k is sensitive to noisy points. Large k is smoother but can blur real boundaries. We choose k by testing on validation data, and an odd k avoids ties between two classes.
Practical tips. k nearest neighbours has no training step: it just stores the data. That makes prediction slow on big datasets. Always scale your features, or large numbers like income will dominate the distance. And it works for regression too, by averaging neighbours.
Recap. To recap. Find the k closest examples and take a vote. Choose k carefully, normalise your features, and remember it is simple and explainable but slow on large data.