Gradient Descent and the Learning Rate
How almost every ML model learns: follow the slope downhill. See small, good and too-large learning rates, and how optimisers like Adam move on a loss surface.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. Almost every machine learning model, from linear regression to giant neural networks, learns with gradient descent. The idea is to walk downhill on the error.
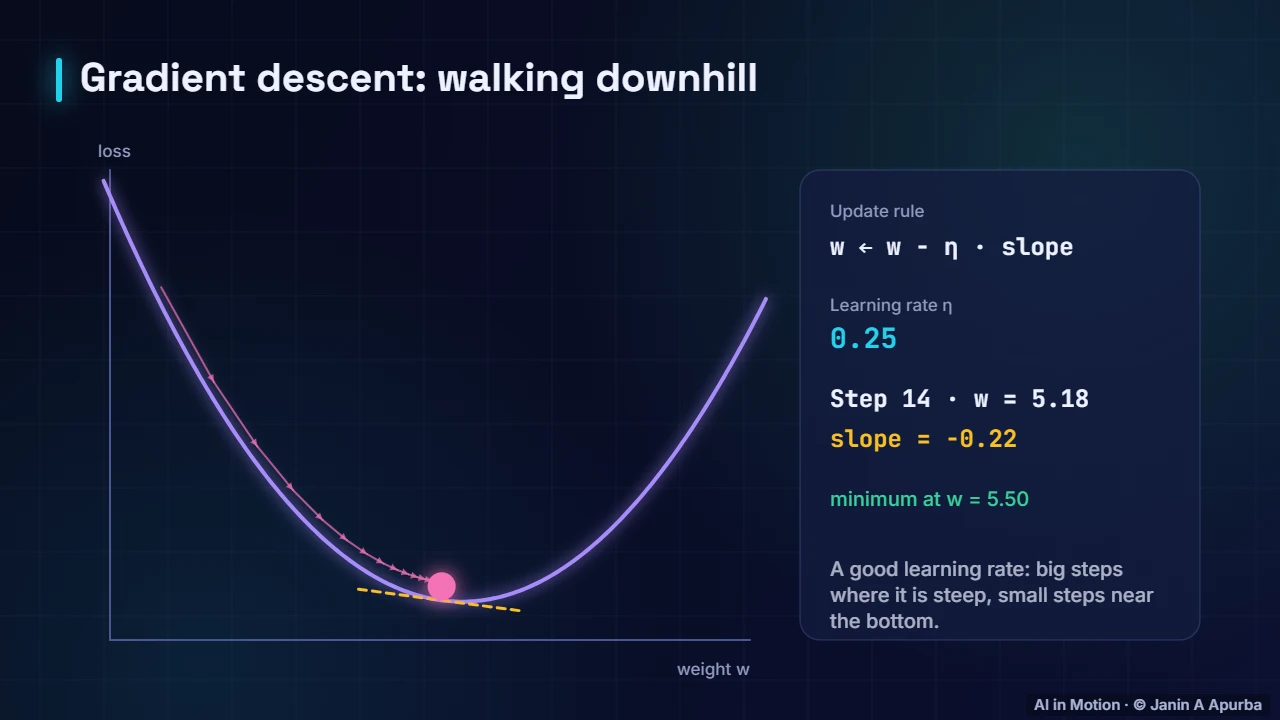
Following the slope. The curve shows the loss for different values of one weight. We measure the slope, the dashed line, and step the opposite way. Where it is steep, steps are big. Near the bottom, the slope flattens and steps shrink automatically.
Update rule. The update rule is short. The new weight equals the old weight, minus the learning rate times the gradient. The minus sign means we always move downhill.
Too small. With a learning rate that is too small, every step is tiny. After fourteen steps, the weight has only crawled to about 2.6, far from the minimum at 5.5. Training would take forever.
Too large. With a learning rate that is too large, each step overshoots the valley. The weight bounces from one side to the other and never settles. The loss does not go down.
Optimisers. Real models have many weights, so the loss is a surface. On this narrow valley, plain gradient descent zigzags from side to side. Adam adapts its step size for each direction and heads almost straight in. Momentum builds up speed along the valley, and by the end it is closest to the minimum.
Recap. To recap. Gradient descent steps against the slope. The learning rate sets the step size, neither too small nor too large. And optimisers like momentum and Adam make the journey faster and smoother.