Linear Regression, Visually
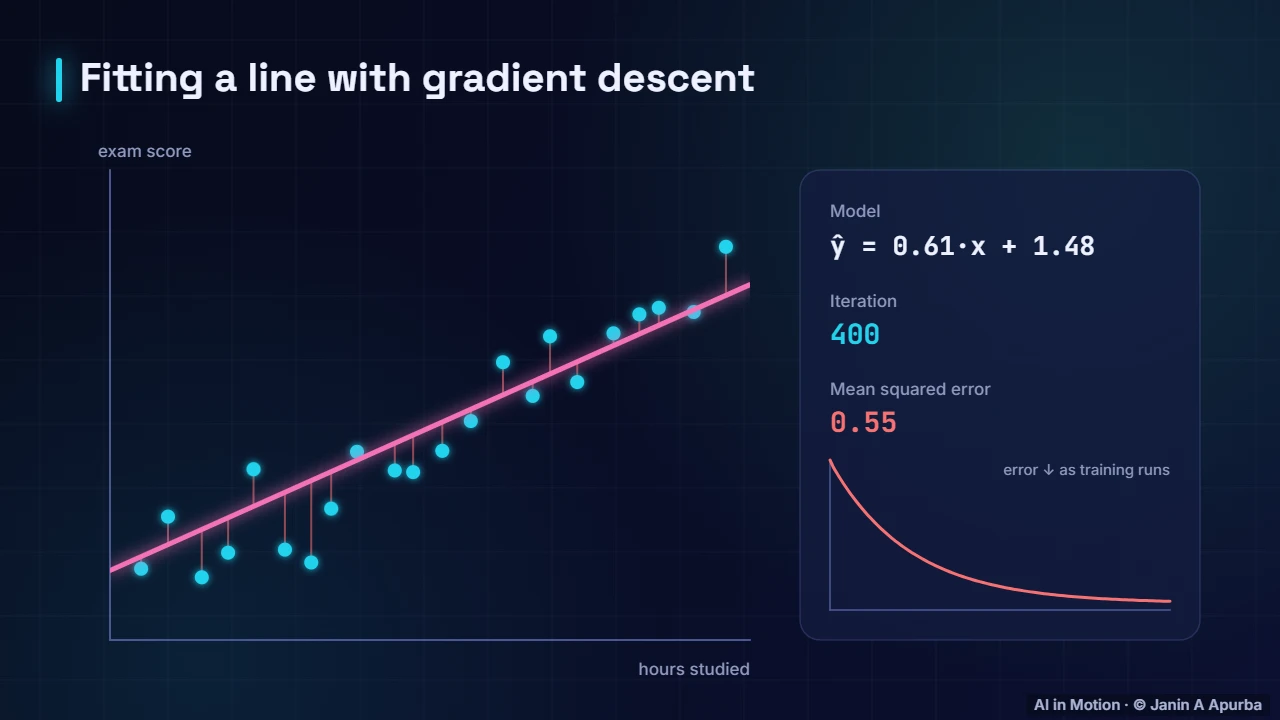
Fit a straight line to data with gradient descent. Watch the residuals shrink and the mean squared error fall from 9.45 to 0.55.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. Does studying longer lead to higher scores? Linear regression answers questions like this by fitting a straight line through data.
The model. The model is a line: y hat equals w times x plus b. W is the slope, how steep the line is. B is the intercept, where it crosses the axis. Training means finding the best w and b.
Fitting the line. The red lines are residuals, the errors between each real score and the prediction. Gradient descent nudges w and b to shrink them. The mean squared error starts at 9.45 and falls to about 0.55 after 400 small steps.
Mean squared error. We measure the fit with the mean squared error. Take each residual, square it so it is positive and big errors count more, then average them. Lower is better.
Strengths and limits. Linear regression is simple, fast and easy to explain. But real relationships are often curved, and a few outliers can drag the line off course. Then we add features or use more flexible models.
Recap. To recap. The model is a line. Residuals are its errors. Mean squared error measures them. And gradient descent finds the best line.