Vanishing Gradients and Residual Connections
Why very deep networks used to be untrainable — gradients shrinking layer by layer — and how skip connections fixed it.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. For years, adding more layers made networks worse, not better. The culprit was the vanishing gradient. Let us watch it happen, and see the fix.
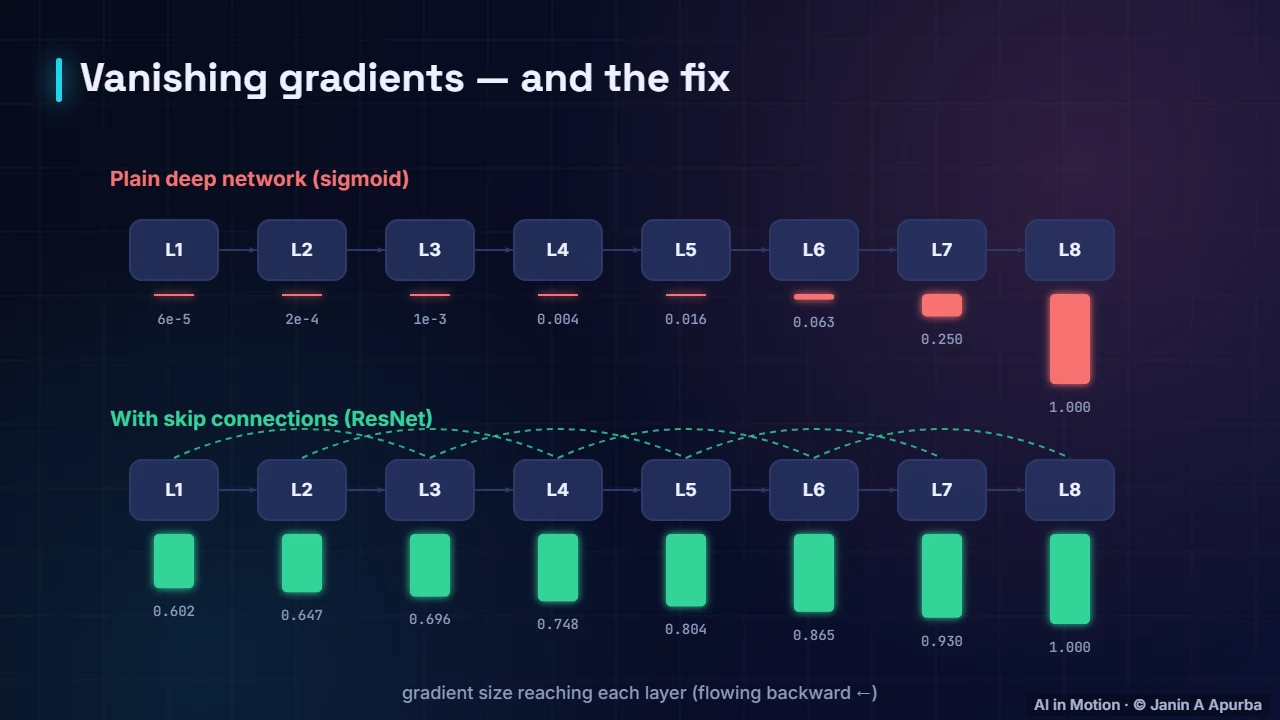
Watching gradients vanish. During backpropagation, the gradient is multiplied by each layer’s local slope on its way back. The sigmoid’s slope is at most 0.25. Multiply by 0.25 again and again, and by the first layer only about 0.00006 of the signal remains. Early layers barely learn.
The maths. With seven layers of sigmoid slopes, the best case is 0.25 to the power 7, which is about 0.00006. Deeper networks make it even smaller. That is why deep sigmoid networks trained so slowly.
Residual connections. Residual networks add skip connections: each block adds its input to its output. The gradient gets a direct highway back through the network. In this illustration it stays around 0.6 even at the first layer. This idea, from ResNet in 2015, made networks with over a hundred layers trainable.
Other fixes. Several tools work together. ReLU activations, careful weight initialisation, normalisation layers, and residual connections. Modern networks, including Transformers, use all of them.
Recap. To recap. Gradients are multiplied layer by layer. Small slopes make them vanish. Skip connections provide a direct path, and that is how very deep networks became trainable.