Dropout and Regularisation
Big networks memorise. Dropout, weight decay, early stopping and augmentation keep them honest — see dropout flicker neurons on and off.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. Neural networks can have millions of parameters, enough to memorise their training data. Regularisation techniques stop that and help them generalise.
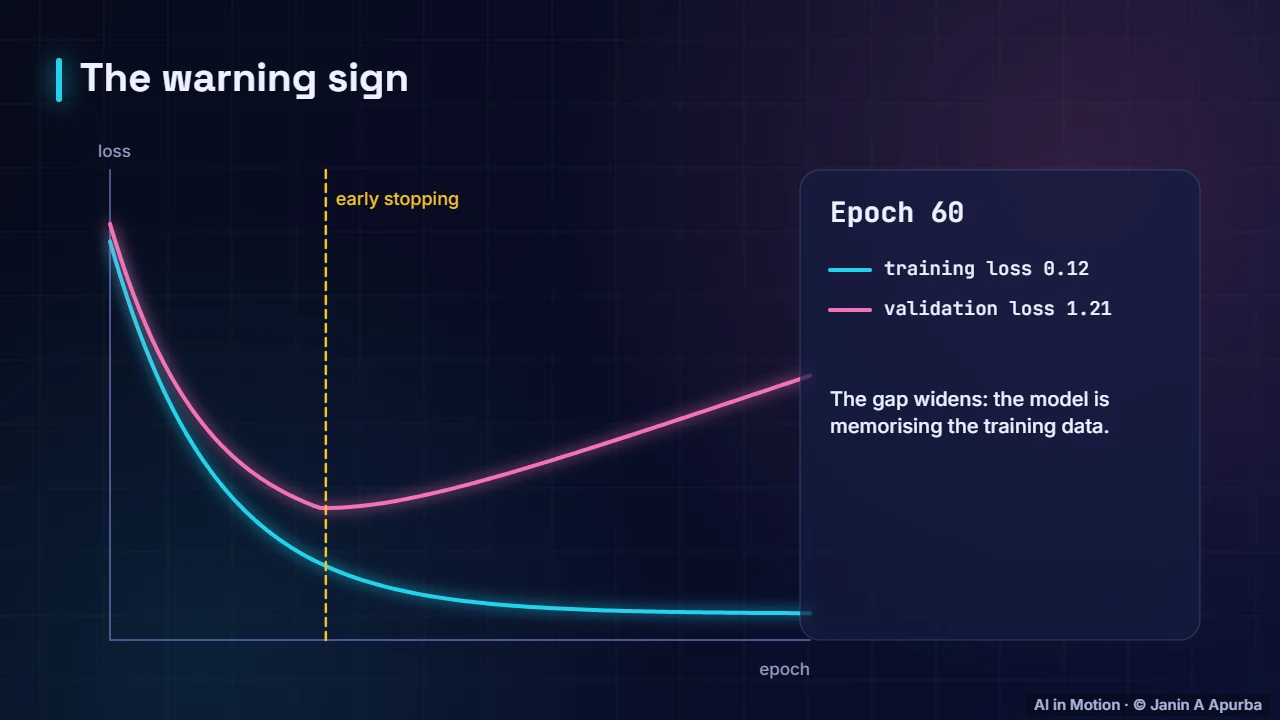
Spotting overfitting. Here is the warning sign. Training loss keeps falling, but validation loss starts to rise. The network is memorising details of the training examples. Early stopping would halt training at the dashed line.
Dropout. Dropout randomly switches off, here, about half of the hidden neurons at every training step. A different random set each time. No neuron can rely on a particular partner, so the network learns more robust, spread-out features. At test time, every neuron is used, with outputs scaled to match.
Toolkit. Other tools include weight decay, which penalises large weights; early stopping; data augmentation, which creates varied training examples; and, most reliable of all, more real data.
Train vs test. During training, dropout is like training many smaller networks that share weights. At test time, using all neurons is like averaging all of them, which usually improves accuracy on new data.
Recap. To recap. Watch for a widening gap between training and validation loss. Dropout, weight decay, early stopping and augmentation all fight overfitting, and more data beats them all.