How AI Image Generators Work
Diffusion models turn pure noise into a picture by removing a little noise at a time, guided by your text prompt.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. Type a description and an AI draws it in seconds. Most of these image generators are diffusion models. Their trick sounds backwards: they create images by removing noise.
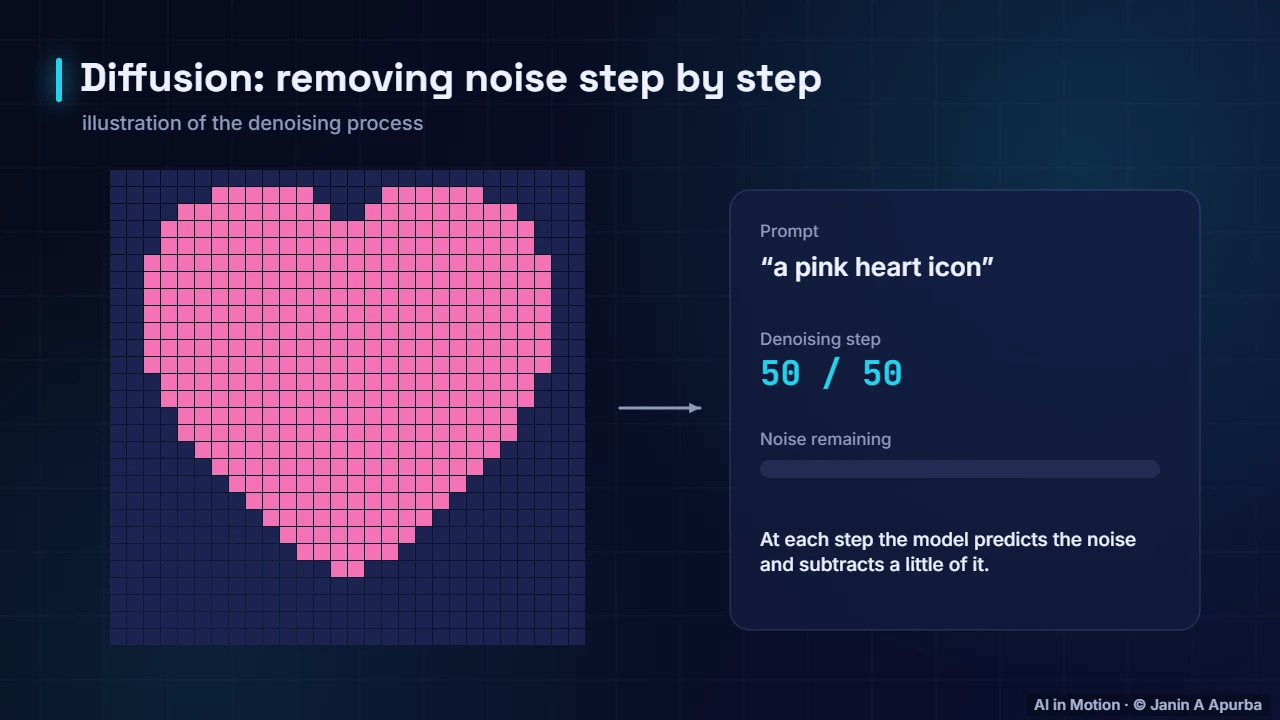
Denoising. Generation starts with random static. At each step, the model predicts which part of the picture is noise and removes a little of it. Slowly, shapes appear, then details sharpen, until the image matches the prompt.
Training. During training, the model sees millions of captioned images. Noise is added to each one, and the network learns to predict exactly which noise was added. Once it is good at that, you can start from pure noise and run the process in reverse.
Guided by text. The text prompt is turned into embeddings, and they guide every denoising step. A different prompt, starting from the same kind of noise, ends in a different picture.
Responsible use. Use these tools responsibly. Check licences, never create images of real people without consent, watch for stereotypes in the results, and label AI images when it matters.
Recap. To recap. Diffusion starts from noise, removes a little predicted noise at every step, is guided by the prompt, and was trained by learning to predict the noise added to real images.