Vision Transformers: Images as Patches
Cut an image into patches, treat them like words and let a Transformer attend between them. How ViTs work and when they beat CNNs.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. Transformers conquered language. In 2020, researchers asked: what if we treat an image like a sentence? The result was the Vision Transformer, or ViT.
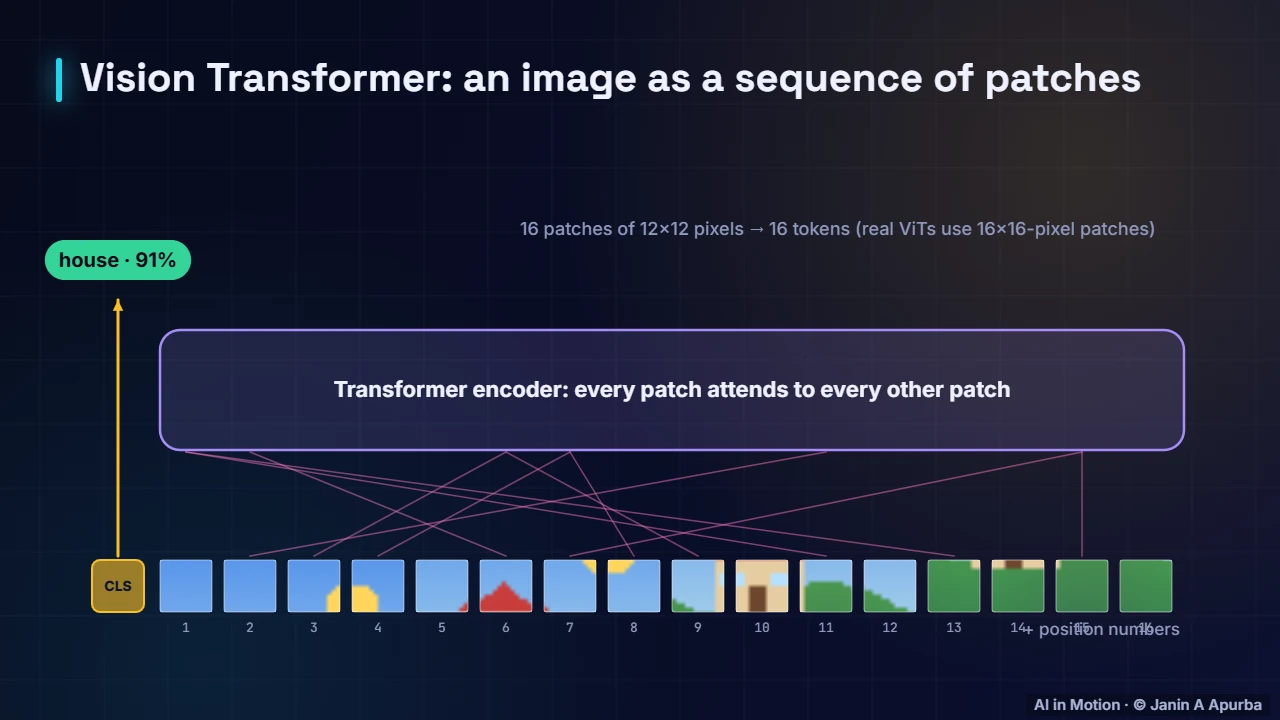
Patches become tokens. The image is cut into a grid of patches. Each patch is flattened and turned into an embedding, just like a word. A position number is added so the model knows where each patch came from, plus a special classification token. The Transformer then lets every patch attend to every other patch, and the classification token gives the answer.
CNNs vs ViTs. CNNs build in assumptions about local patterns, so they learn well from less data. Vision transformers have fewer built-in assumptions and see the whole image from the first layer. They shine when pre-trained on huge datasets, and they power many of today’s vision foundation models.
Attention. Inside, it is the same attention we saw for words. Each patch builds its understanding by weighing every other patch, so distant parts of the image can inform each other directly.
Foundation models. Vision transformers underpin CLIP, which connects images and text, self-supervised methods like DINO and MAE, promptable segmentation like Segment Anything, and multimodal assistants that can discuss images.
Recap. To recap. Split into patches, embed them with positions, add a classification token, and let attention do the rest. Vision transformers shine with large-scale pre-training.