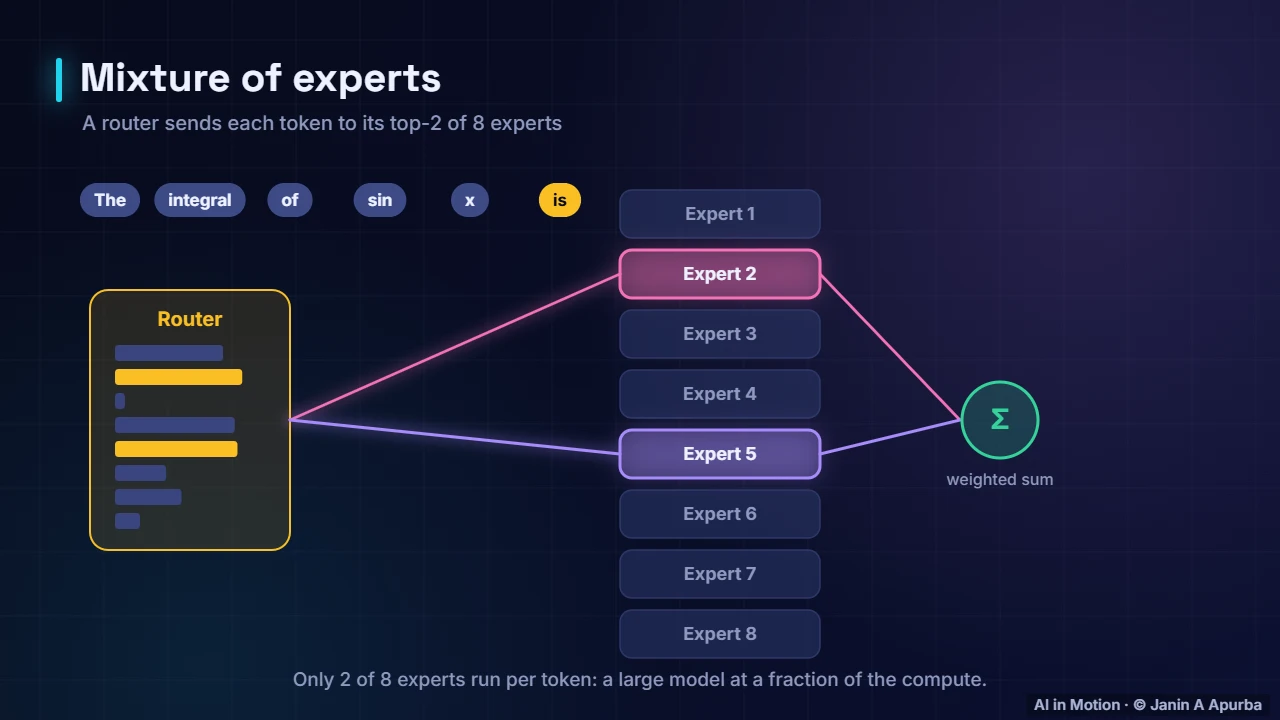
Mixture of Experts
A router sends each token to a few specialised experts, so a model can have many parameters while using only a fraction per token.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. What if a model could be huge, but only use a small part of itself for each word? That is the idea behind mixture of experts.
Routing tokens. Inside each mixture of experts layer there are several feed-forward networks, the experts, and a small router. For every token, the router scores all eight experts and sends the token to the best two. Their outputs are combined as a weighted sum. Different tokens go to different experts.
Dense vs MoE. In a dense model every parameter works on every token. In a mixture of experts, only the chosen experts run, so total capacity grows without the compute growing as fast. For example, Mixtral 8 by 7B uses two of its eight experts for each token.
Challenges. There are challenges. The router must spread tokens fairly so some experts are not overloaded, which is handled with a load balancing loss. All experts must still fit in memory, and moving tokens between GPUs adds communication.
Recap. To recap. A router sends each token to a few experts, their outputs are combined, and the model gains capacity without proportional compute, as long as load and memory are managed.