Landmark CNNs: From LeNet to ResNet
The architectures that defined deep vision — and how ImageNet top-5 error fell from 28% to under 4% in five years.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. A handful of famous networks shaped modern computer vision. Each one introduced an idea we still use today.
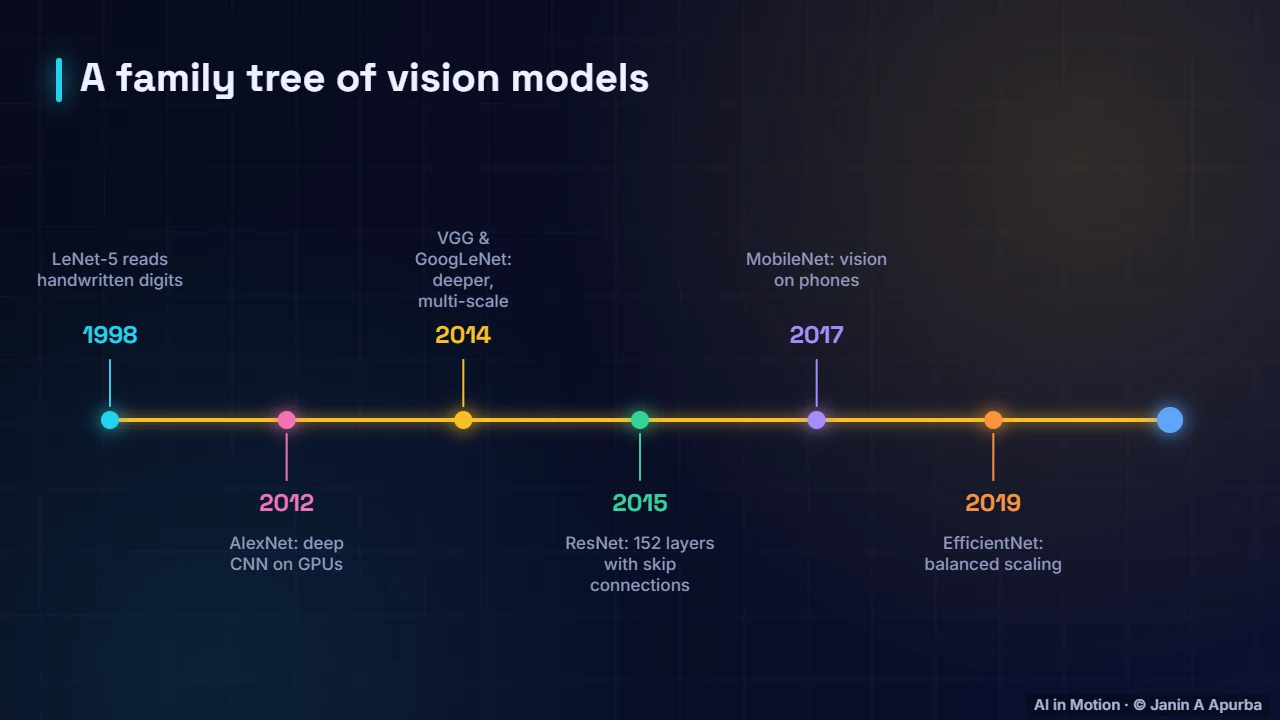
The timeline. LeNet read handwritten digits in 1998. AlexNet in 2012 showed deep CNNs trained on GPUs could win big. VGG and GoogLeNet went deeper in 2014. ResNet reached 152 layers in 2015. MobileNet brought vision to phones, EfficientNet balanced scaling, and in 2020 the Vision Transformer arrived.
The ImageNet race. The ImageNet challenge asked models to recognise a thousand categories. The winning top five error was 28 percent in 2010. AlexNet cut it to 16.4 percent in 2012. By 2015, ResNet reached about 3.6 percent, below one published estimate of human error, around 5 percent.
Key ideas. Each network added an idea. AlexNet used ReLU, dropout and GPUs. VGG stacked small three by three filters. GoogLeNet mixed several filter sizes in parallel. ResNet added skip connections. And MobileNet and EfficientNet optimised accuracy per unit of computation.
ResNet’s trick. ResNet’s trick was the skip connection. Gradients flow back through shortcut paths instead of fading layer by layer, which made networks with over a hundred layers trainable.
Recap. To recap. LeNet and AlexNet started it. VGG, GoogLeNet and ResNet went deeper and smarter. ImageNet error fell from 28 percent to about 3.6. And efficient networks and transformers are the next chapters.