Activation Functions: Sigmoid, Tanh and ReLU
Why networks need non-linearity, and how sigmoid, tanh, ReLU, Leaky ReLU and GELU differ — drawn live.
📄 Illustrated notes · every chapter as a picture · printable
Quick quiz
3 questions to check your understanding.
Go deeper
University-level written lectures in The AI Lecture Hall:
Transcript
Introduction. Without activation functions, even a hundred-layer network would only learn straight-line relationships. Activation functions add the bends that make deep learning powerful.
Why they matter. Stacking linear layers just gives another linear function, so depth would be pointless. Non-linear activations break that, letting networks model curves, corners and complex decision boundaries.
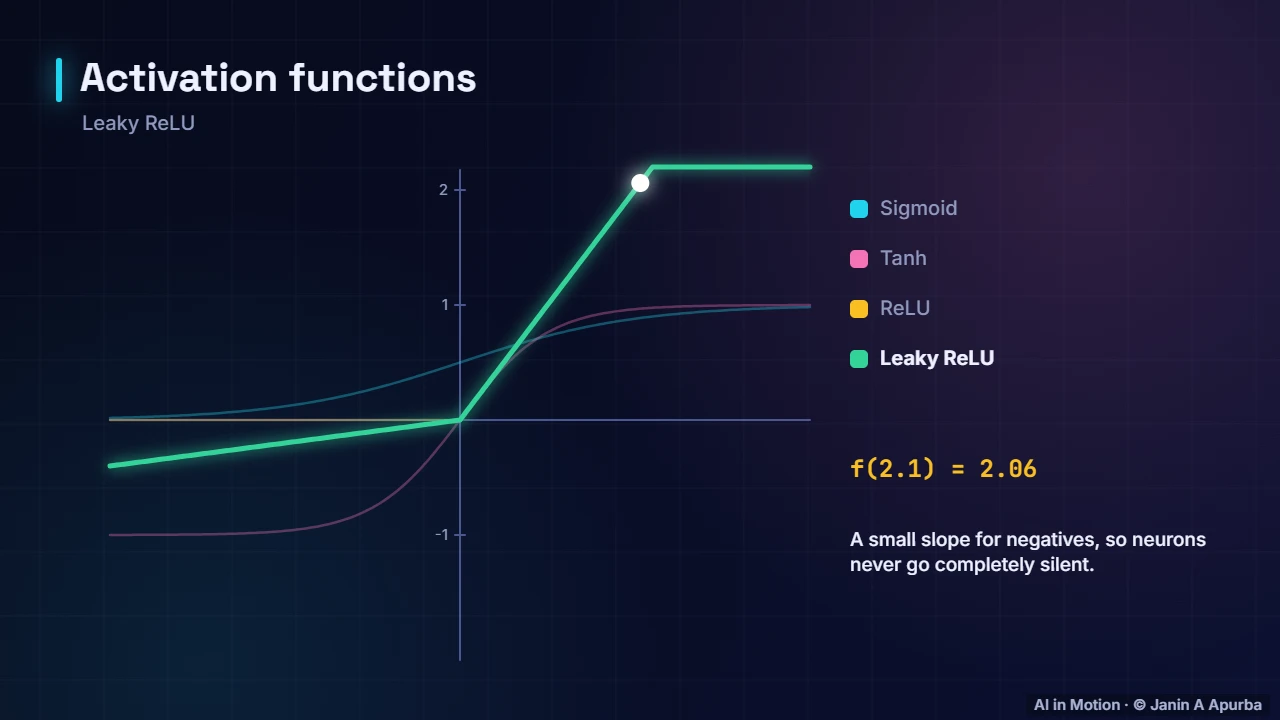
Four classics. The sigmoid squeezes values between zero and one. Tanh is similar but centred on zero. ReLU outputs zero for negative inputs and passes positive ones straight through. Leaky ReLU keeps a small slope for negatives, so neurons never die completely.
Vanishing gradients. Sigmoid and tanh flatten out for large inputs, where their slope is almost zero. During training, those tiny slopes multiply through many layers and gradients vanish. ReLU keeps a slope of one for positive inputs, so gradients flow much better.
Modern choices. Modern networks often use ReLU, or smooth variants like GELU, which is common in Transformers. For outputs we use sigmoid for yes or no answers and softmax for choosing between many classes.
Recap. To recap. Activations add non-linearity. Sigmoid and tanh can make gradients vanish. ReLU and its variants are the usual default. And output layers use sigmoid or softmax.