Tokenization and Byte-Pair Encoding — lecture notes
Words, characters or sub-words? See three ways to tokenise text, then watch byte-pair encoding learn sub-words from a tiny corpus.
0:001. Introduction
Before a model can read a sentence, the sentence must be cut into pieces called tokens. How we cut it matters more than you might think.
0:112. Three strategies
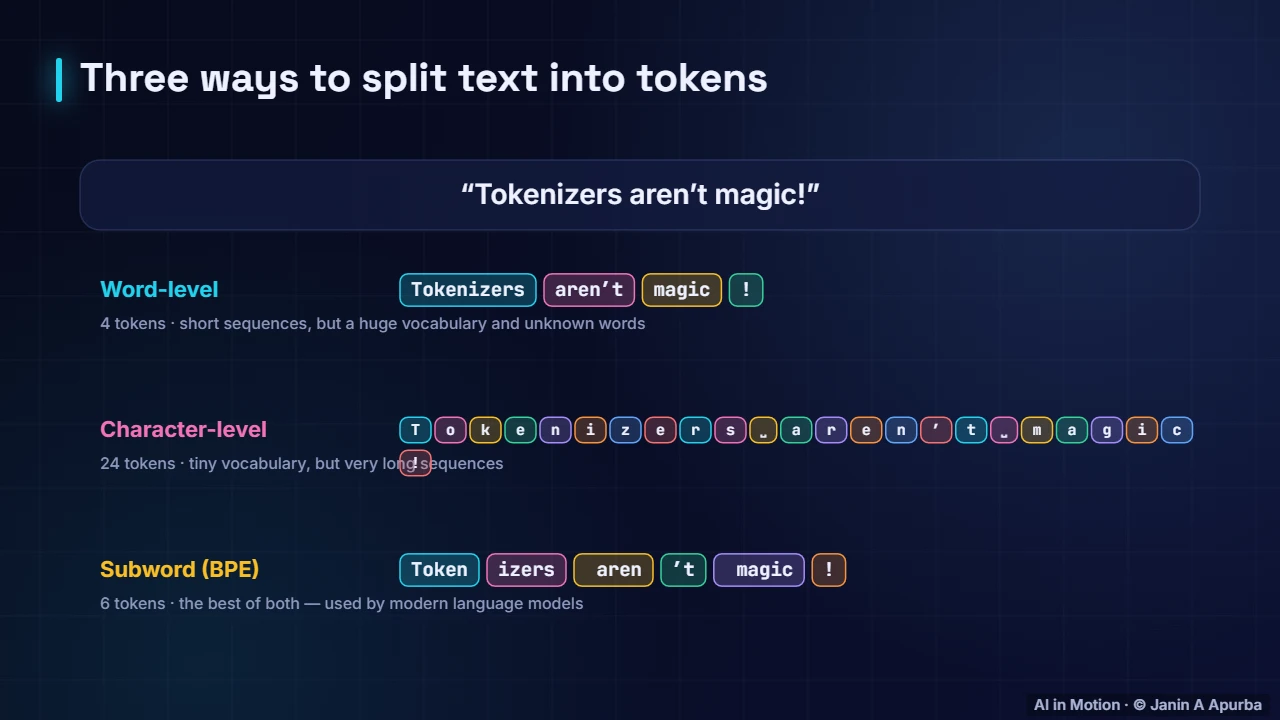
Word-level tokenization gives short sequences, but needs a huge vocabulary and cannot handle new words. Character-level needs only a tiny vocabulary, but sequences become very long. Sub-word tokenization sits in between: common words stay whole, rare words split into meaningful pieces.
0:293. Byte-pair encoding
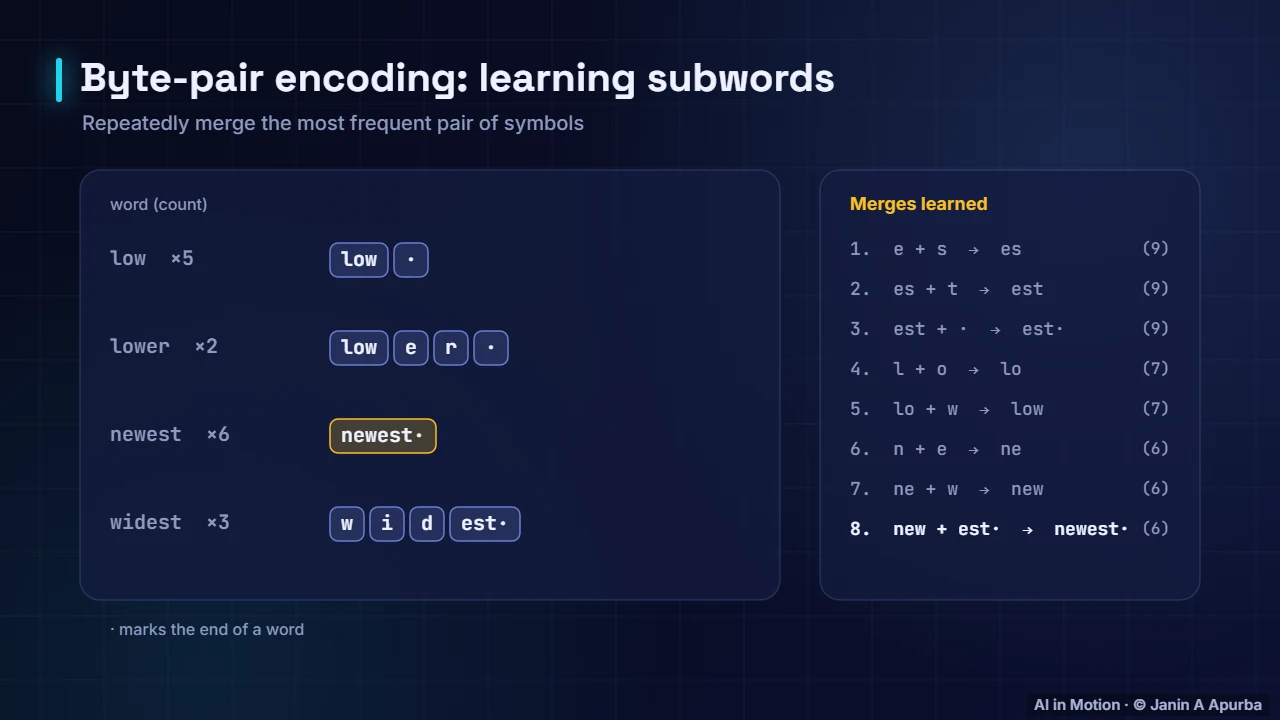
Byte-pair encoding learns sub-words from data. Start with single characters. Count every adjacent pair, weighted by word frequency, and merge the most frequent one. Here e and s appear together nine times, so they merge first, then e s with t, then est with the end of a word. Repeat, and useful pieces like est and low emerge.
0:534. Why sub-words
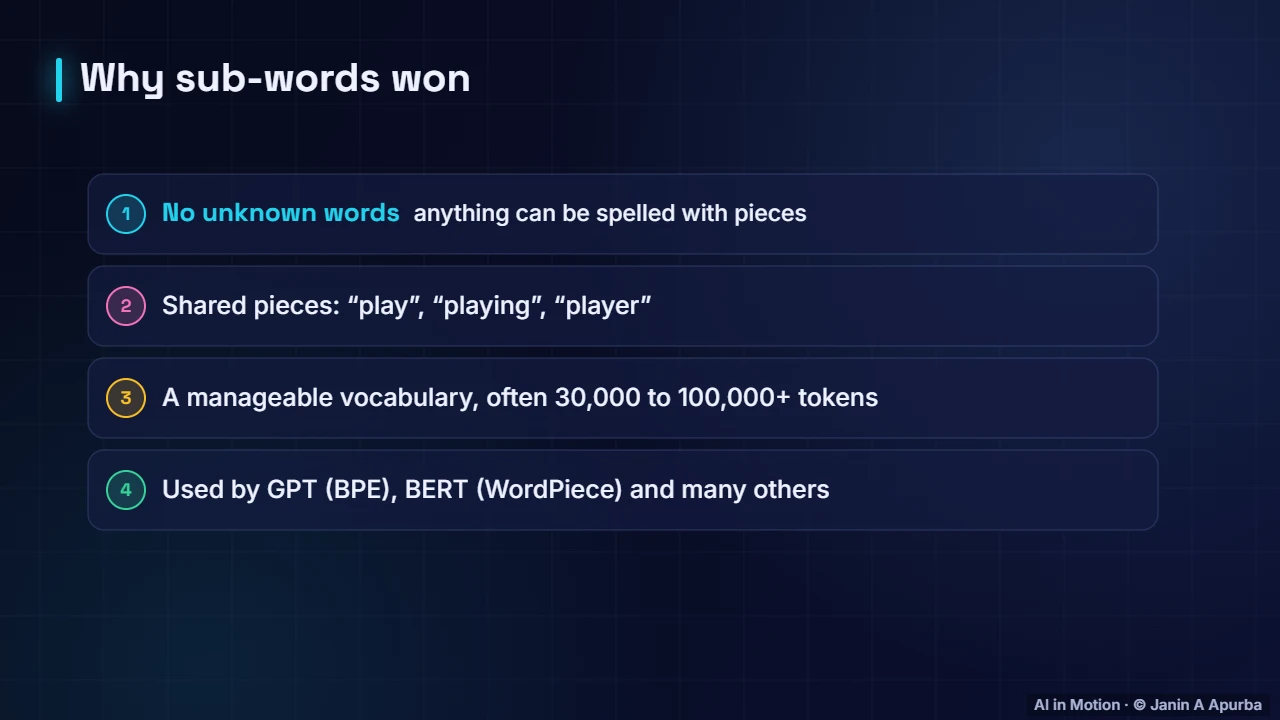
Sub-words mean no word is ever unknown, because anything can be spelled from pieces. Related words share pieces, and the vocabulary stays manageable. GPT models use byte-pair encoding, and BERT uses a close cousin called WordPiece.
1:095. In practice
In English, a token is roughly three quarters of a word on average. Many other languages need more tokens for the same meaning. Model limits and prices are counted in tokens, and tokenization even explains why language models struggle to count letters in a word.
1:286. Recap
To recap. Tokens are what models read. Sub-word tokenization is the modern standard, and byte-pair encoding builds it by repeatedly merging the most frequent pair of symbols.
Key takeaways
- Tokenization splits text into units (tokens) that a model processes.
- Sub-word tokenization balances vocabulary size and sequence length.
- BPE repeatedly merges the most frequent adjacent pair; in the demo e+s (9 times) merges first.
- In English, a token is about ¾ of a word on average.
Check yourself
- What does each BPE step do?
Show answer
Merges the most frequent adjacent pair of symbols — BPE builds sub-words by merging the most common pair.
- A key advantage of sub-word tokenization is…
Show answer
It can represent any word, even unseen ones — Unknown words can be spelled from known pieces.
- Why can character-level models be slow?
Show answer
Sequences become very long — Every character is a separate token.
Go deeper
- Text Preprocessing: Tokenisation, Normalisation, Stemming and Lemmatisation · The AI Lecture Hall
- Subword Tokenisation: BPE, WordPiece, Unigram and SentencePiece · The AI Lecture Hall
© 2026 Janin A Apurba, CSE, AUST · Advanced ICT Officer, CNRS-UNHCR. All rights reserved. Notes for the animated lecture at https://ai-in-motion.vercel.app/watch/tokenization-and-subwords.html