Quantisation: Smaller, Faster Models — lecture notes
Store each weight in fewer bits. See weights snap to int8 and int4 levels, and how a 7B model shrinks from 28 GB to 3.5 GB.
0:001. Introduction
Large models are heavy. A seven billion parameter model in full precision needs about 28 gigabytes just for its weights. Quantisation makes it much smaller.
0:112. Snapping to levels
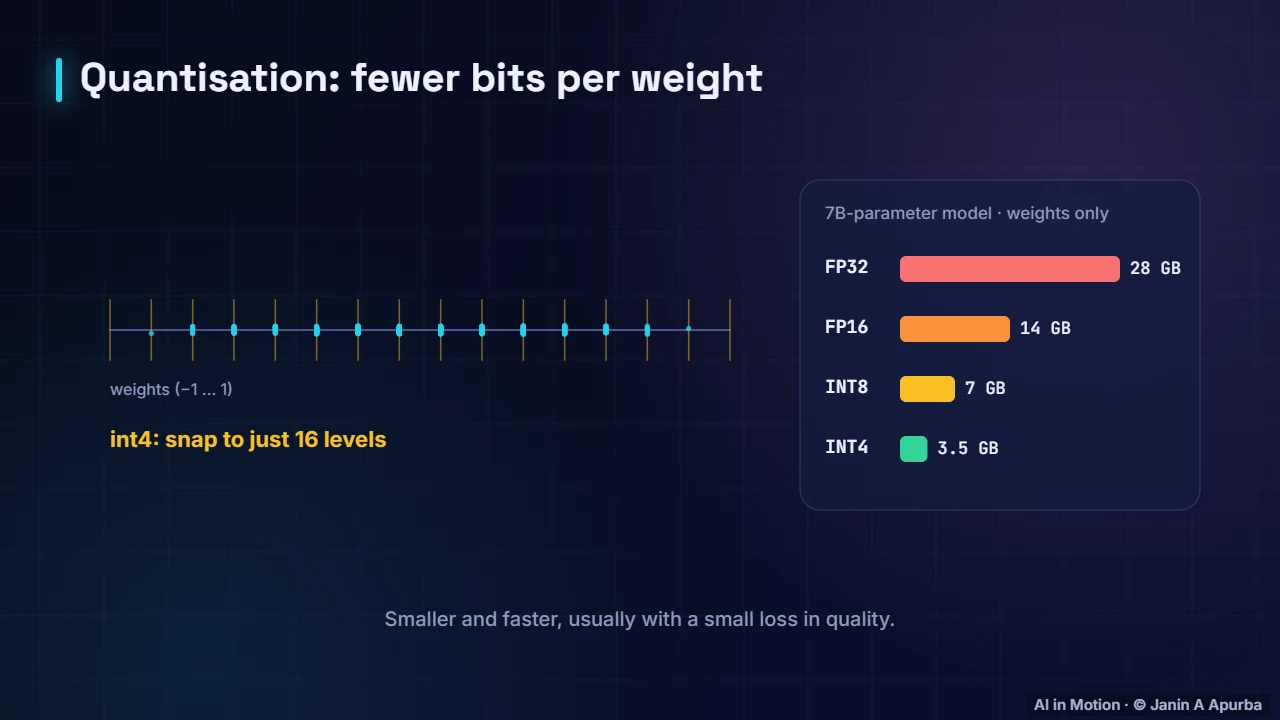
Normally each weight is a 32-bit floating point number. Int8 quantisation snaps every weight to one of 256 levels. Int4 uses only 16 levels. Memory for a seven billion parameter model falls from 28 gigabytes to 14 in 16-bit, 7 in 8-bit and 3.5 in 4-bit.
0:313. The formula
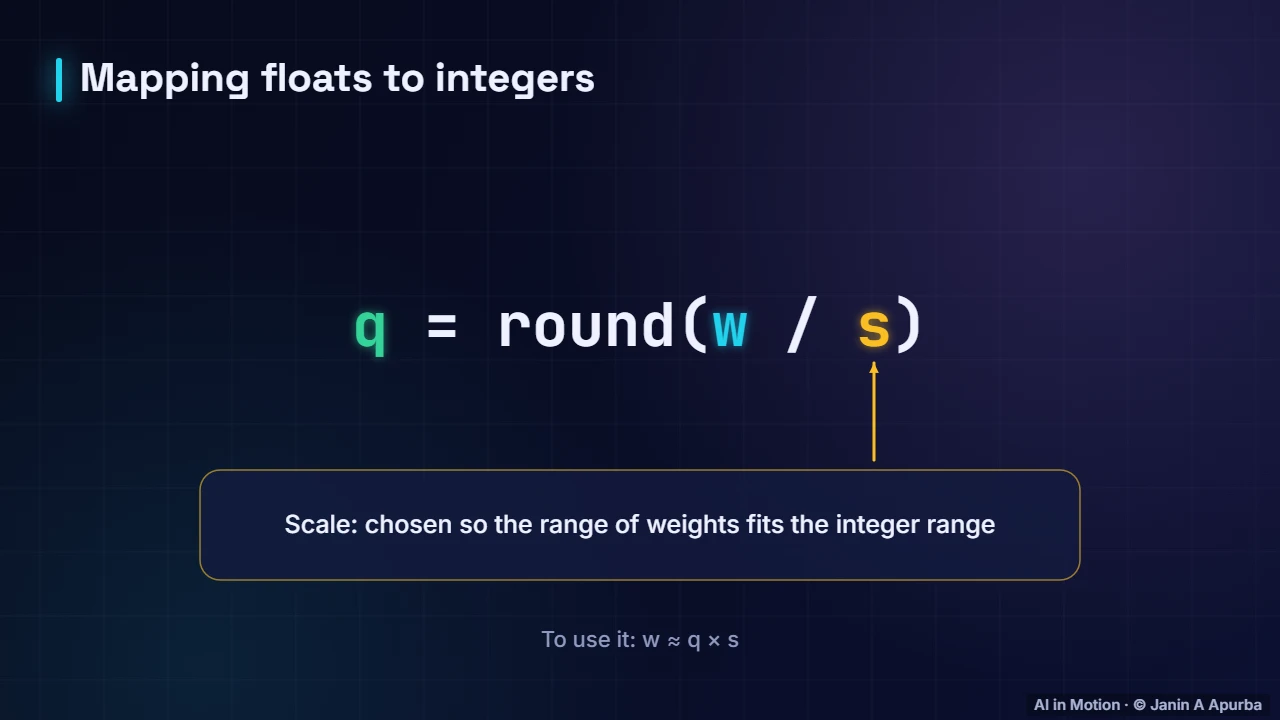
Each weight is divided by a scale factor and rounded to the nearest integer. To use it, multiply back by the scale. The rounding error is the price we pay. Good methods choose scales per group of weights to keep errors small.
0:494. Trade-offs
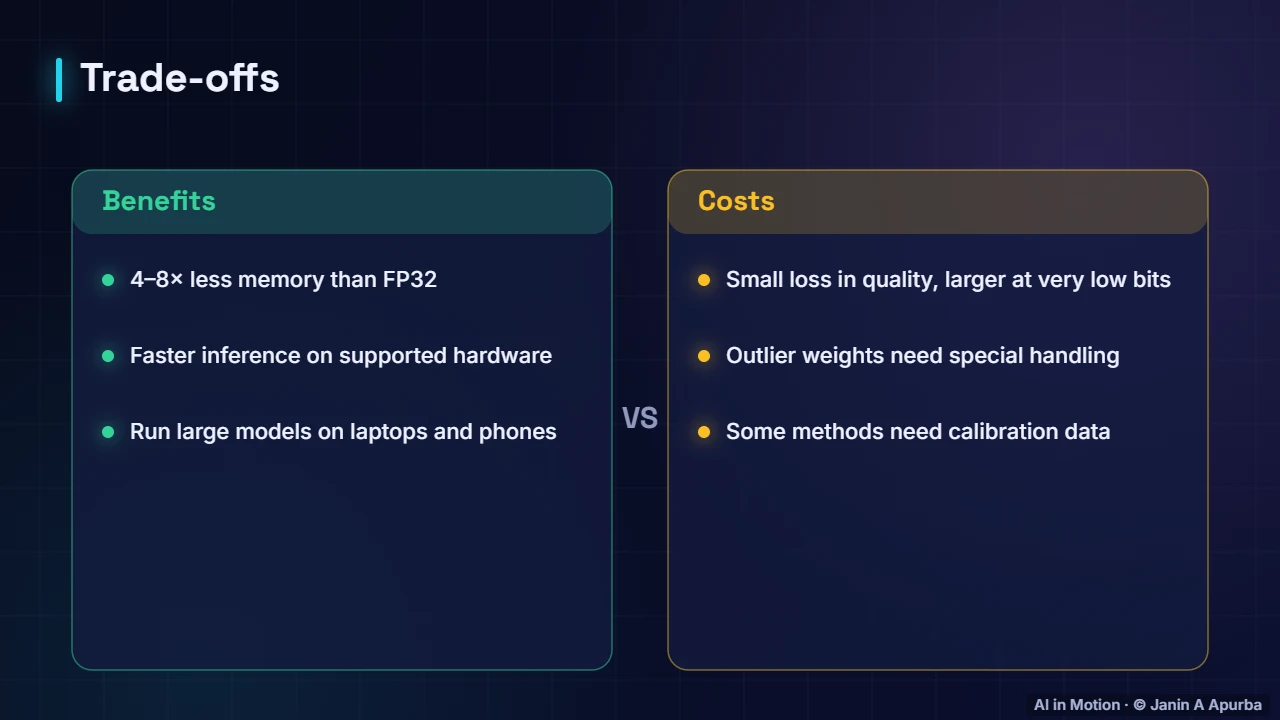
Quantisation cuts memory and often speeds up inference, making large models run on laptops and phones. The cost is a small drop in quality, larger at very low bit widths, and outlier weights need careful handling.
1:045. Recap
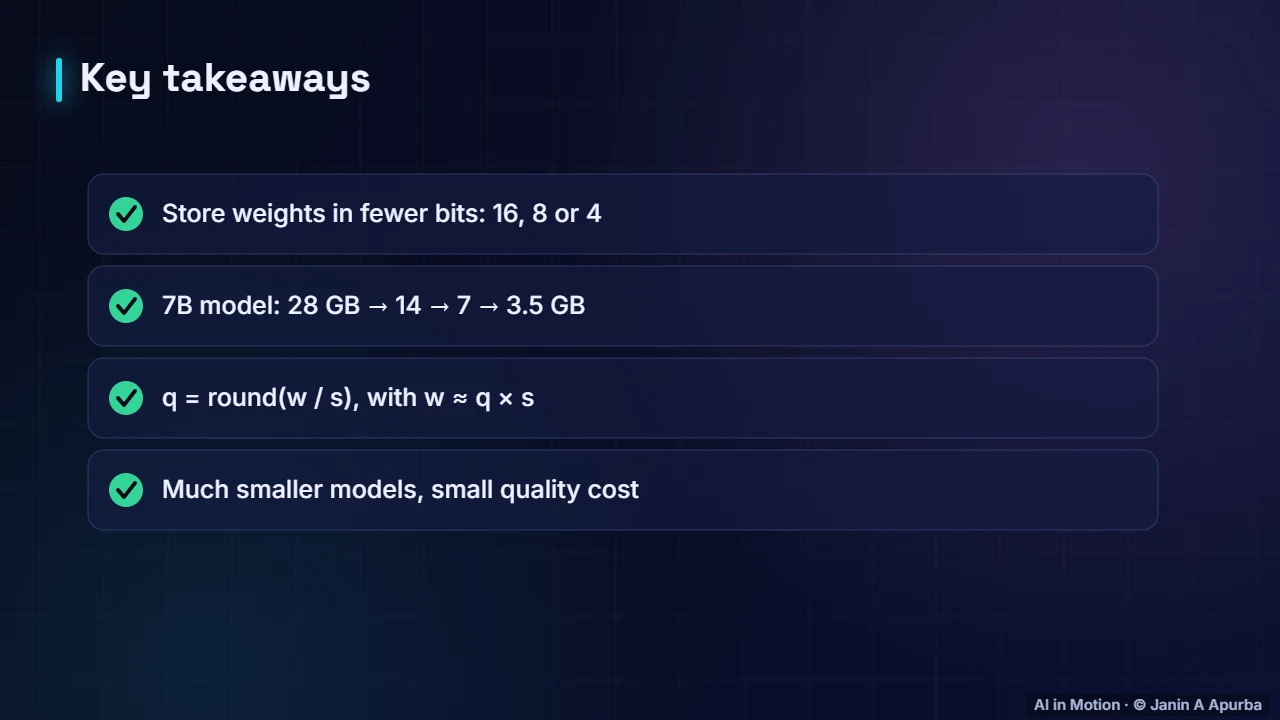
To recap. Quantisation stores weights in fewer bits, shrinking a seven billion parameter model from 28 gigabytes to 3.5, with a small cost in quality.
Key takeaways
- Quantisation stores weights with fewer bits (e.g. 16, 8 or 4).
- A 7B-parameter model needs about 28 GB in FP32, 14 GB in FP16, 7 GB in INT8 and 3.5 GB in INT4 (weights only).
- Weights are scaled and rounded: q = round(w / s).
- It trades a small loss of quality for large memory and speed gains.
Check yourself
- How much memory do the weights of a 7B model need in INT4?
Show answer
About 3.5 GB — 7 billion × 0.5 bytes = 3.5 GB.
- How many distinct levels can a 4-bit integer represent?
Show answer
16 — 2⁴ = 16.
- What is the main cost of quantisation?
Show answer
A small loss in accuracy from rounding — Rounding introduces small errors.
Go deeper
- Quantising Large Language Models for Efficient Inference · The AI Lecture Hall
- LLM Inference: KV Caching, Batching and Speculative Decoding · The AI Lecture Hall
- Model Compression: Pruning and Quantisation · The AI Lecture Hall
© 2026 Janin A Apurba, CSE, AUST · Advanced ICT Officer, CNRS-UNHCR. All rights reserved. Notes for the animated lecture at https://ai-in-motion.vercel.app/watch/quantization.html