N-gram Language Models — lecture notes
Predict the next word by counting word pairs. A bigram model built from a tiny corpus — the ancestor of today’s LLMs.
0:001. Introduction
A language model predicts the next word. Today that is done by giant neural networks, but the idea started with simple counting.
0:102. A bigram model
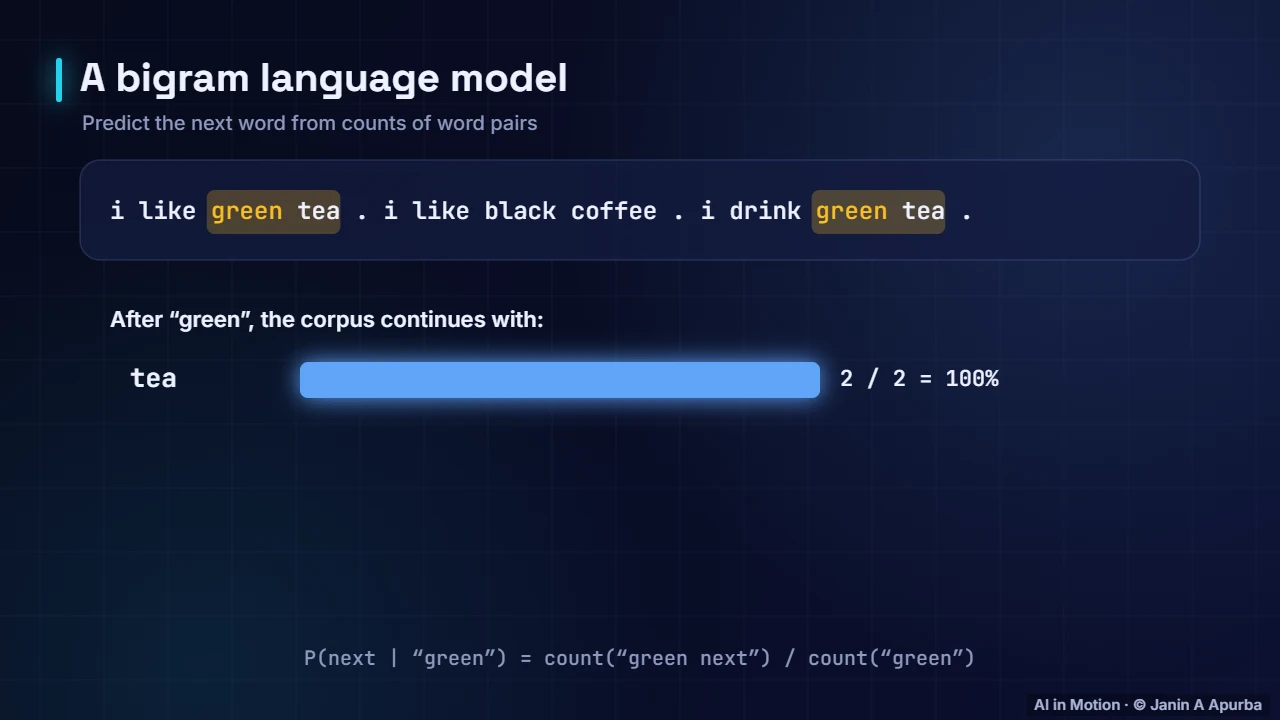
Here is a tiny corpus. A bigram model looks at pairs of words. After the word i, the corpus continues with like twice and drink once, so the probability of like is two thirds. After like, green and black are equally likely. After green, it is always tea.
0:303. The formula
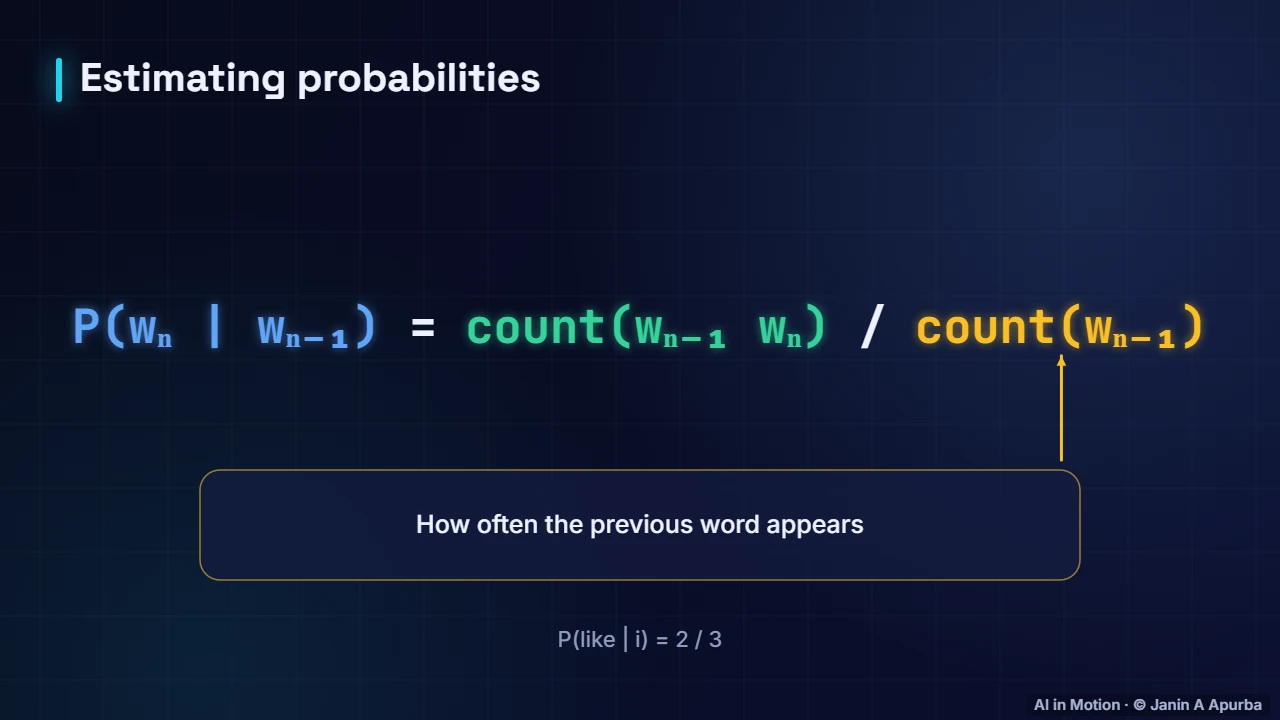
The probability of the next word, given the previous one, is the count of the pair divided by the count of the previous word. Like after i: two divided by three.
0:444. Limitations
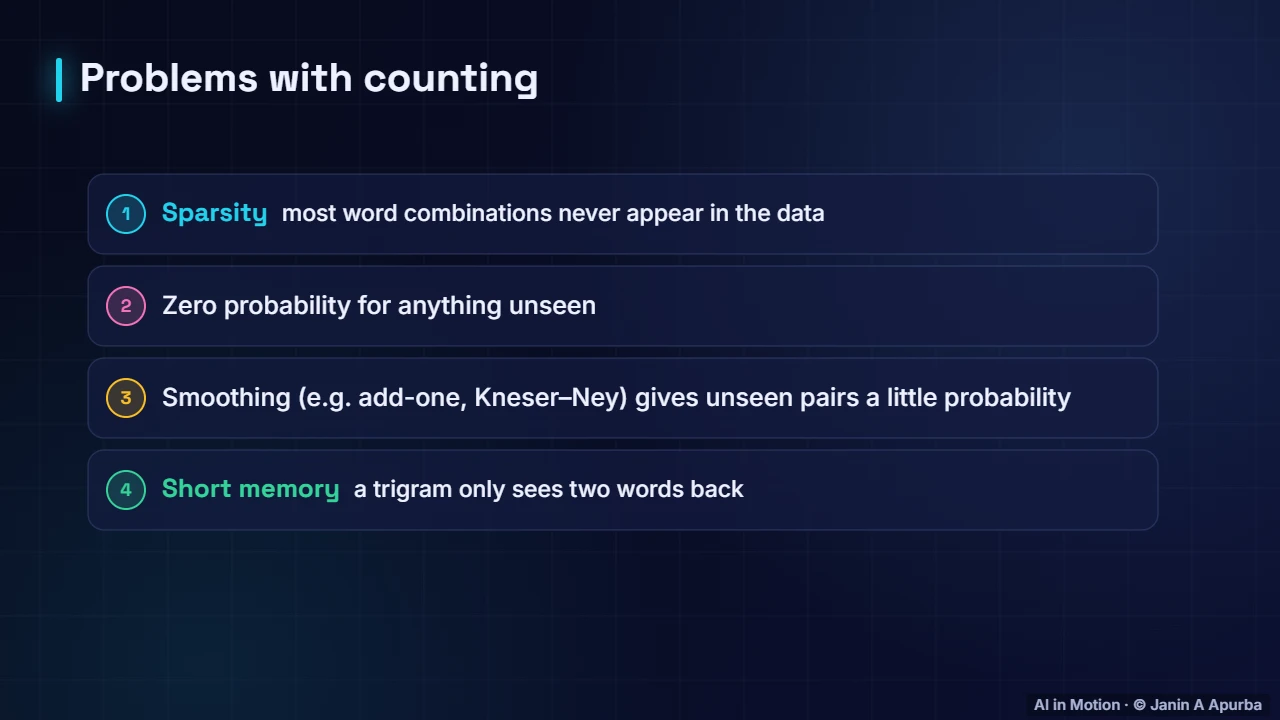
Counting has problems. Most word combinations never appear, so they get zero probability. Smoothing techniques give unseen pairs a little probability. And n-grams have short memory: a trigram only sees two words back.
0:585. From counts to neural
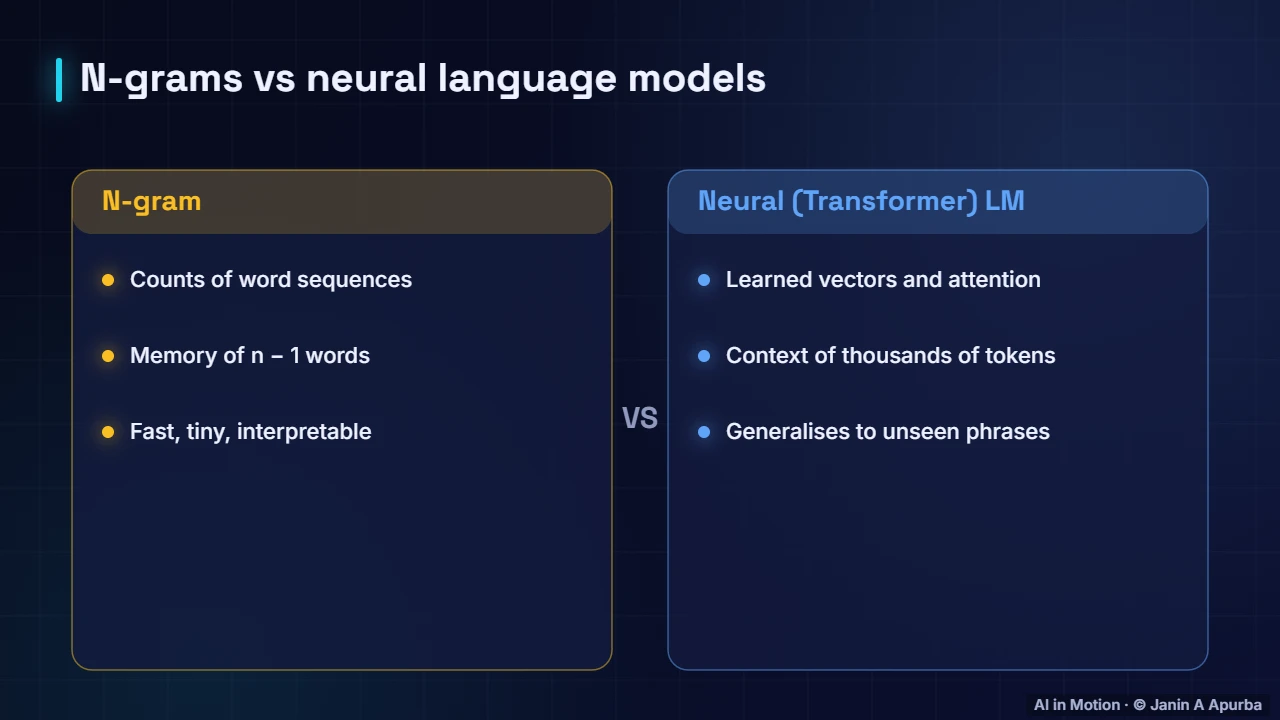
Neural language models replace counts with learned vectors, generalise to phrases they have never seen, and use attention to look back across thousands of tokens. But the goal is the same: predict the next word.
1:146. Recap
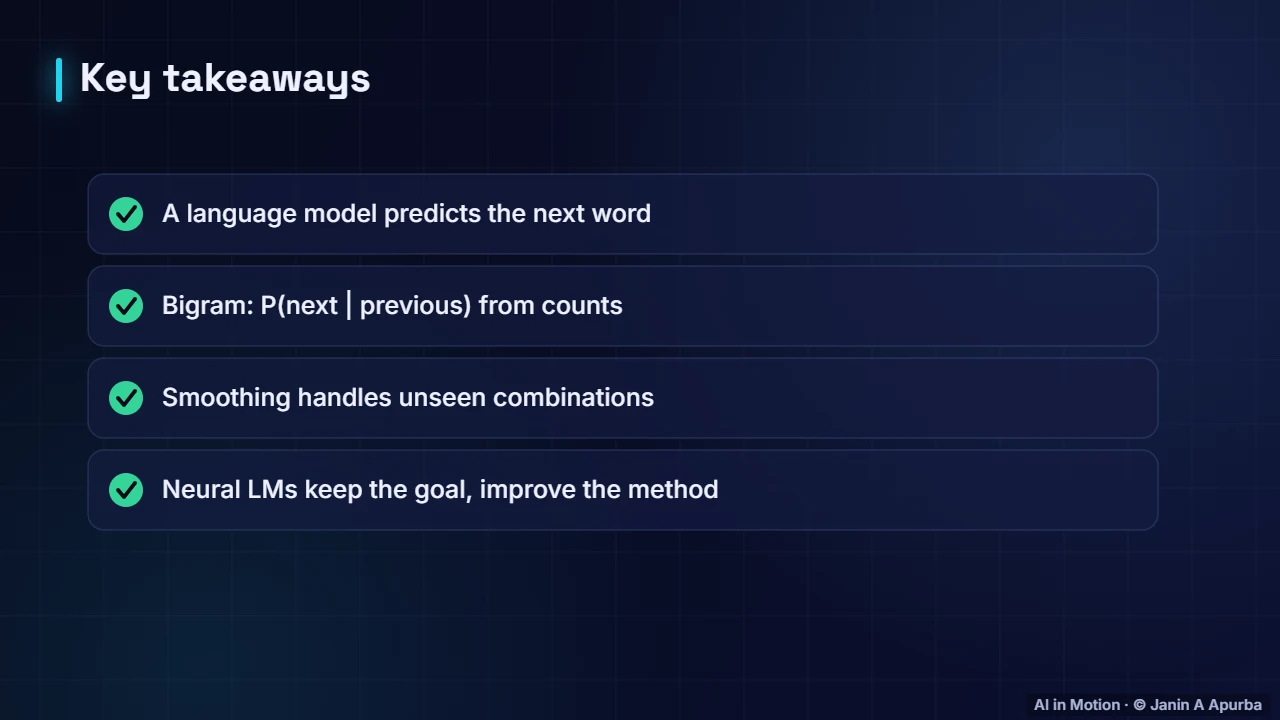
To recap. A language model predicts the next word. N-grams do it by counting. Smoothing handles unseen pairs. And modern neural models pursue the same goal with far more context.
Key takeaways
- A language model assigns probabilities to the next word.
- Bigram: P(wₙ | wₙ₋₁) = count(wₙ₋₁ wₙ) / count(wₙ₋₁); in the demo P(like | i) = 2/3.
- Unseen combinations get zero probability unless smoothed.
- Neural language models keep the same objective with much longer context.
Check yourself
- In the corpus, “i” is followed by “like” 2 times and “drink” once. What is P(like | i)?
Show answer
2/3 — 2 out of 3 occurrences.
- What problem does smoothing solve?
Show answer
Zero probability for unseen word combinations — It reserves some probability for unseen n-grams.
- How much context does a trigram model use?
Show answer
The previous 2 words — A trigram conditions on n − 1 = 2 previous words.
Go deeper
- N-gram Language Models, Smoothing and Perplexity · The AI Lecture Hall
- Evaluating NLP Systems: Perplexity, BLEU, ROUGE, BERTScore and Human Judgement · The AI Lecture Hall
© 2026 Janin A Apurba, CSE, AUST · Advanced ICT Officer, CNRS-UNHCR. All rights reserved. Notes for the animated lecture at https://ai-in-motion.vercel.app/watch/n-gram-language-models.html