Loss Functions and the Training Loop — lecture notes
How a network measures its mistakes and improves: mini-batches, forward pass, loss, backward pass and update — repeated thousands of times.
0:001. Introduction
A freshly created network makes random guesses. Training turns it into something useful through one loop, repeated thousands of times.
0:092. The loss
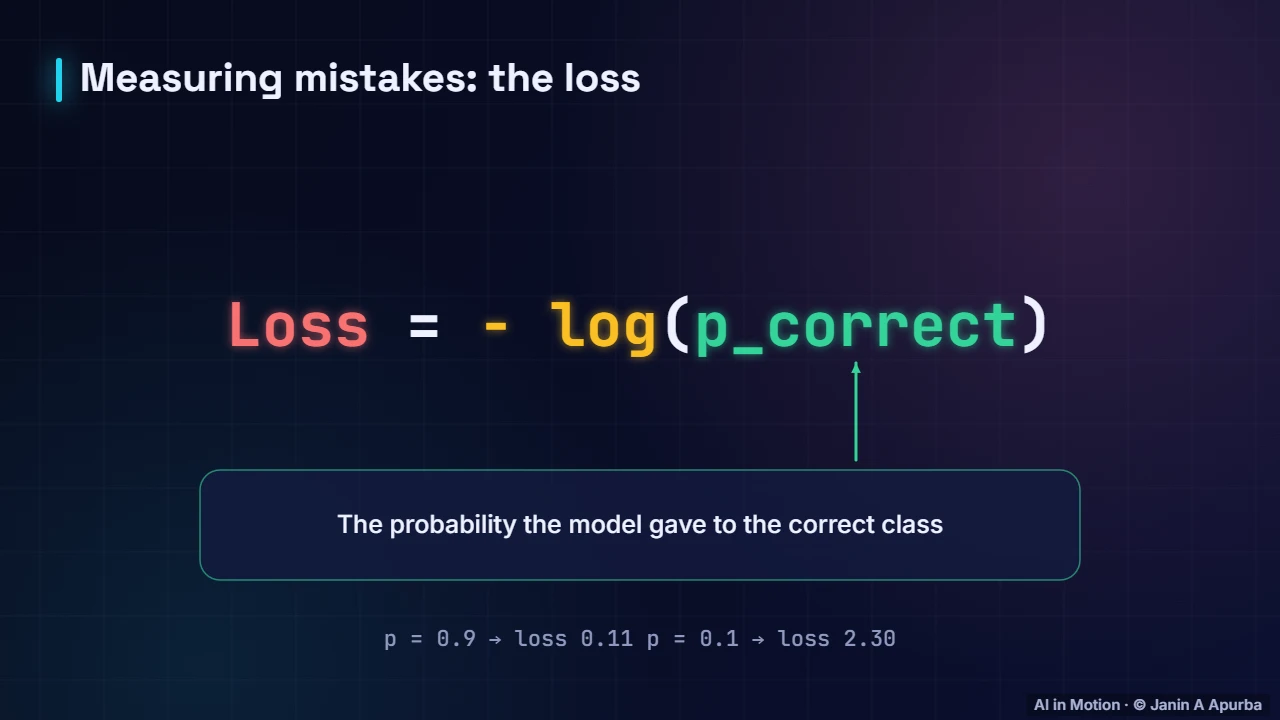
First we need a single number that says how wrong the network is: the loss. For classification we usually use cross-entropy: minus the log of the probability given to the correct answer. If the model gives the right class 90 percent, the loss is 0.11. If it gives only 10 percent, the loss is 2.3.
0:323. The loop
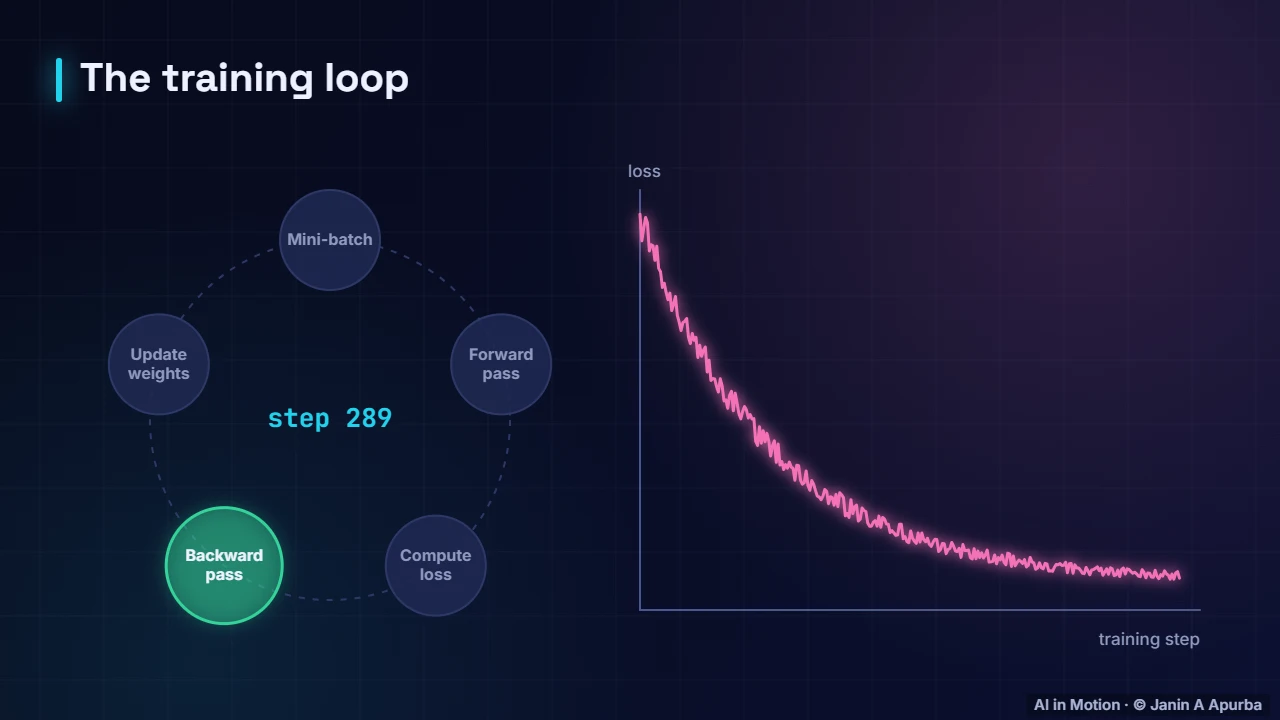
Here is the loop. Take a mini batch of examples. Run a forward pass to get predictions. Compute the loss. Run a backward pass to find how each weight affects the loss. Update the weights a little. Then take the next batch. The loss on the right falls as training goes on.
0:544. Key terms
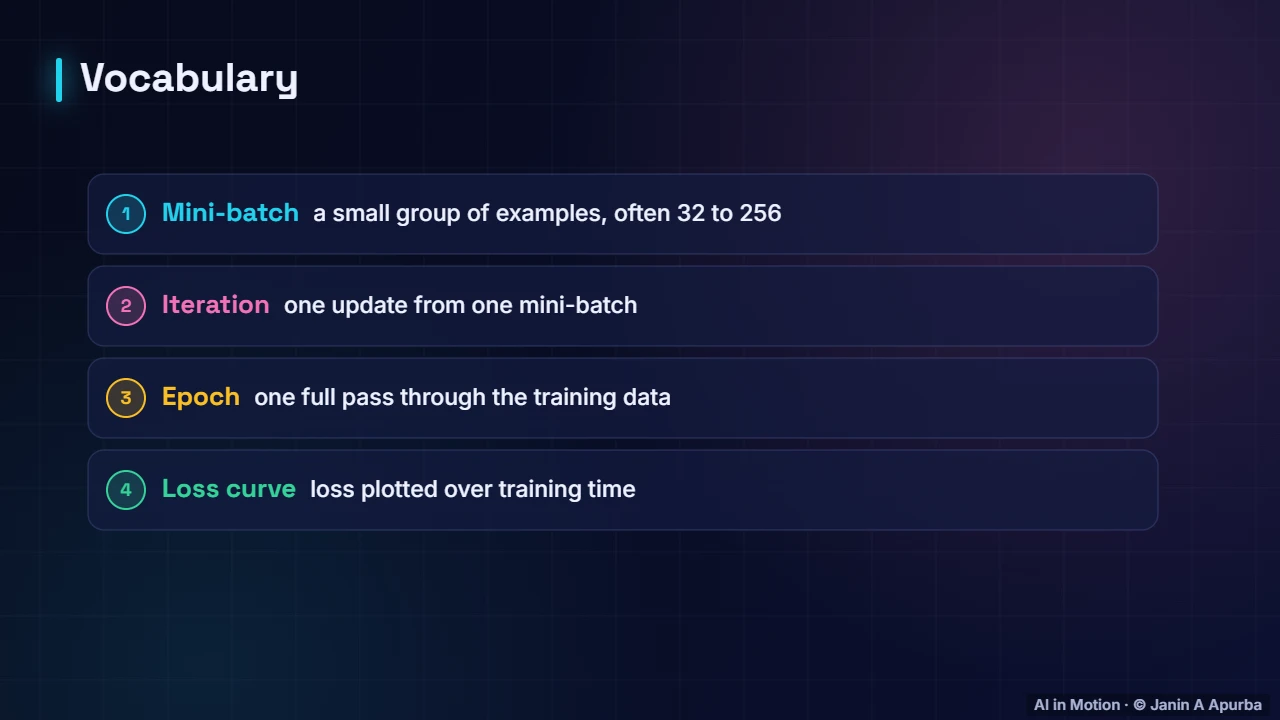
Some vocabulary. A mini batch is a small group of examples. One iteration is one update. An epoch is one full pass through all the training data. And the loss curve tracks progress.
1:095. Watching progress
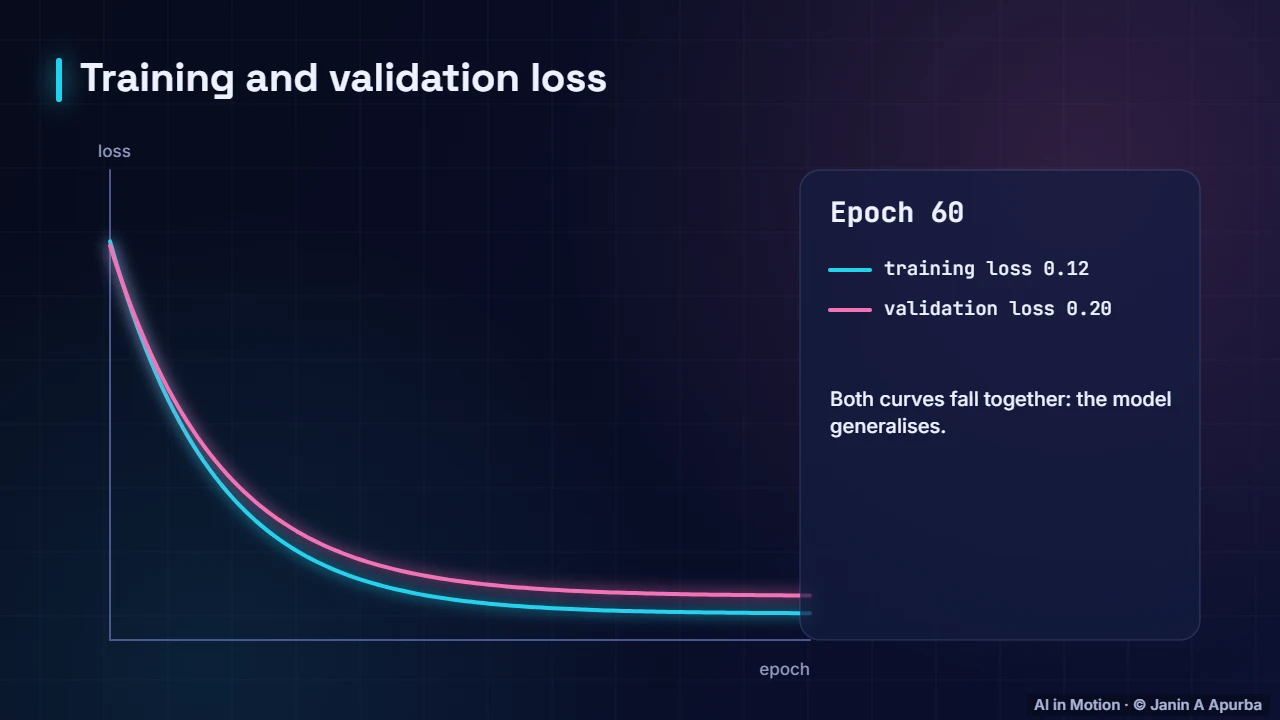
We always watch two curves: loss on the training data and loss on validation data the model does not learn from. When both fall together, the network is genuinely learning, not just memorising.
1:236. Recap
To recap. The loss measures mistakes. Cross-entropy for classes, mean squared error for numbers. The loop is batch, forward, loss, backward, update. And we watch both training and validation loss.
Key takeaways
- The loss turns prediction errors into one number to minimise.
- Cross-entropy: −log(p_correct); p = 0.9 gives 0.11, p = 0.1 gives 2.30.
- Training repeats: mini-batch, forward, loss, backward, update.
- An epoch is one pass through all the training data.
Check yourself
- If the model assigns probability 0.9 to the correct class, the cross-entropy loss is about…
Show answer
0.11 — −ln(0.9) ≈ 0.105.
- What is an epoch?
Show answer
One full pass through the training data — An epoch covers every training example once.
- Which step computes how each weight affects the loss?
Show answer
The backward pass — Backpropagation computes the gradients.
Go deeper
- Loss Functions in Deep Learning: What Are We Really Optimising? · The AI Lecture Hall
- PyTorch Fundamentals: Tensors, Autograd, Modules and the Training Loop · The AI Lecture Hall
- Debugging Neural Network Training: A Systematic Recipe · The AI Lecture Hall
© 2026 Janin A Apurba, CSE, AUST · Advanced ICT Officer, CNRS-UNHCR. All rights reserved. Notes for the animated lecture at https://ai-in-motion.vercel.app/watch/loss-functions-and-the-training-loop.html