Decoding: Temperature, Top-k and Top-p — lecture notes
How a language model picks each word from its probabilities — and how temperature, top-k and top-p change its personality.
0:001. Introduction
A language model outputs probabilities for the next token. How we pick from them, called decoding, changes whether the text is safe and predictable or creative and surprising.
0:122. Temperature
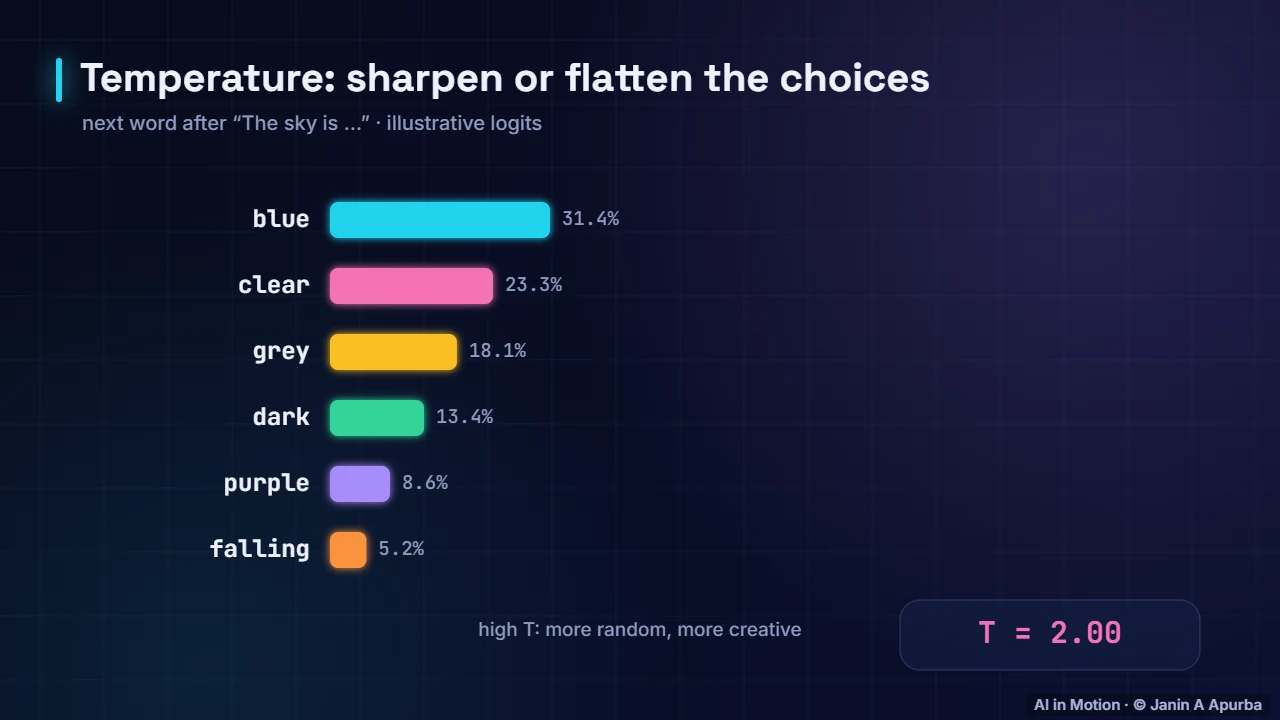
After the sky is, the model gives blue 46 percent at temperature one. Lower the temperature to 0.4, and the distribution sharpens: blue jumps to about 77 percent. Raise it to 2 and it flattens: blue falls to about 31 percent, and unusual words like purple get a real chance.
0:333. The formula
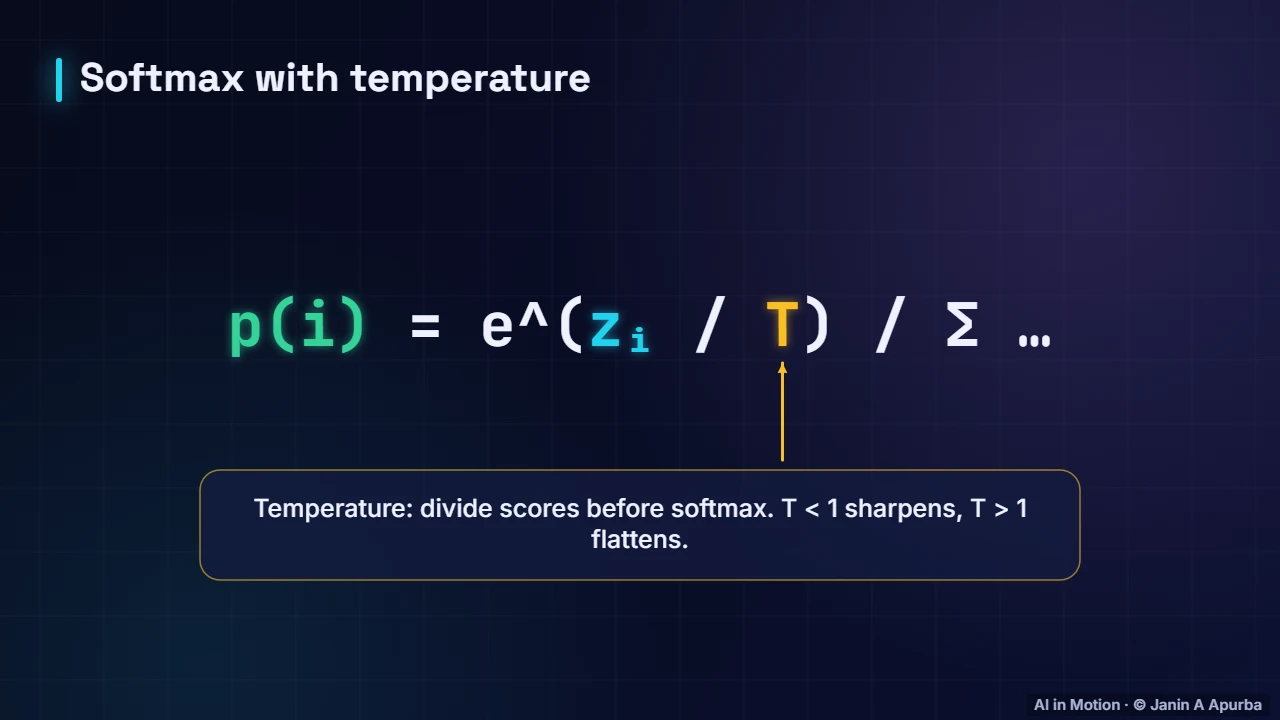
Temperature simply divides the raw scores before the softmax. Below one, differences grow and the top choice dominates. Above one, differences shrink and choices even out.
0:454. Top-k and top-p
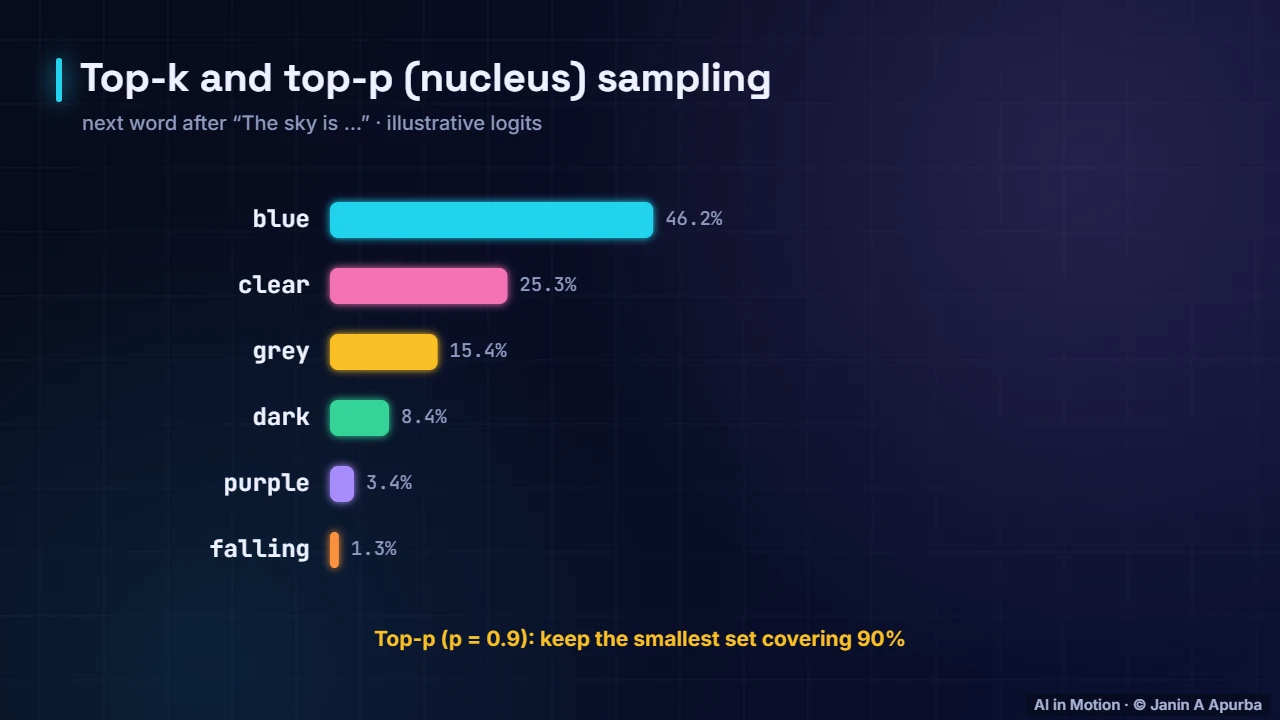
Top k keeps only the k most likely tokens, here three, and samples among them. Top p, or nucleus sampling, keeps the smallest set whose probabilities add up to 90 percent. Here that is four tokens. Both cut off the long tail of unlikely, often nonsensical choices.
1:055. Practical settings
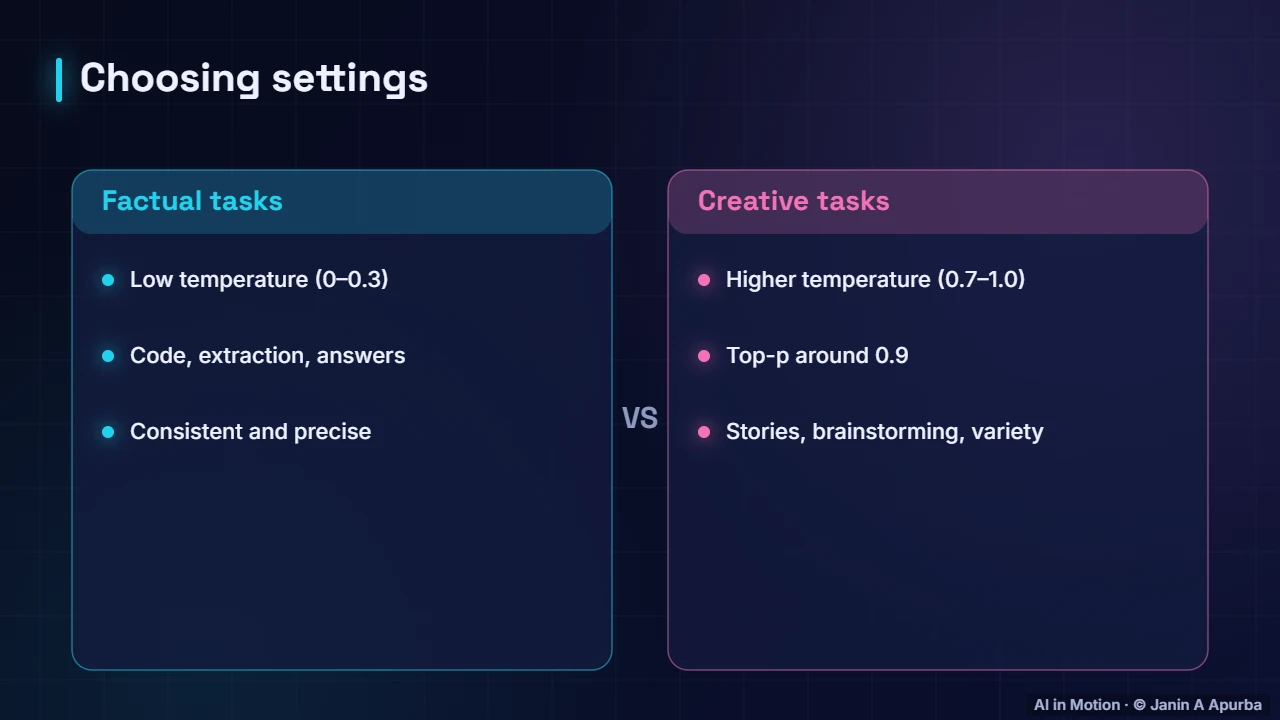
For factual work like code or data extraction, use a low temperature for consistent answers. For brainstorming and stories, a higher temperature with top p around 0.9 gives variety without nonsense.
1:196. Recap
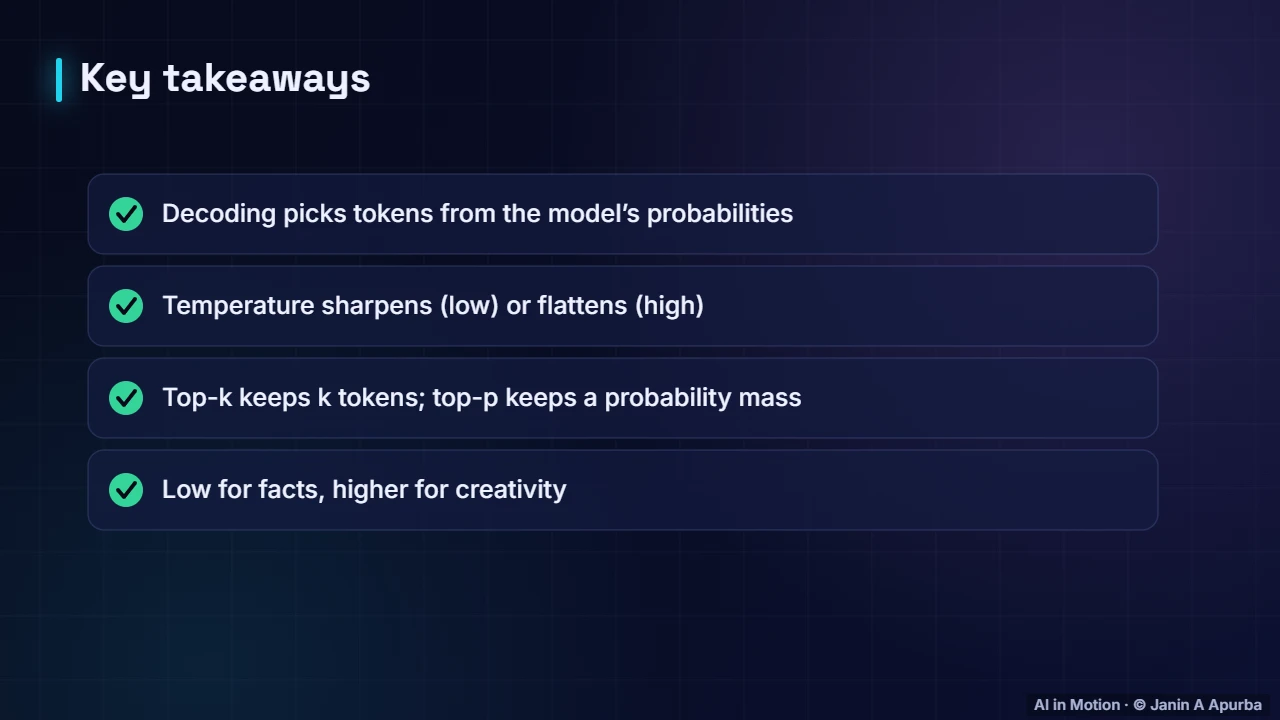
To recap. Decoding chooses from probabilities. Temperature sharpens or flattens them. Top k and top p trim the unlikely tail. Low for facts, higher for creativity.
Key takeaways
- Temperature divides logits before softmax: T < 1 sharpens, T > 1 flattens.
- In the demo “blue” is 76.7% at T = 0.4, 46.2% at T = 1 and 31.4% at T = 2.
- Top-k keeps the k most likely tokens; top-p keeps the smallest set covering p of the probability.
- Use low temperature for factual tasks and higher for creative ones.
Check yourself
- What does lowering the temperature do?
Show answer
Makes the top choice even more likely — Dividing by a small T exaggerates differences.
- Top-p = 0.9 keeps…
Show answer
The smallest set of tokens whose probabilities sum to at least 90% — Nucleus sampling uses cumulative probability.
- Which setting suits extracting data from invoices?
Show answer
Low temperature — Precision matters more than variety.
Go deeper
- Decoding Strategies: Greedy, Beam Search, Temperature, Top-k and Top-p · The AI Lecture Hall
- Large Language Models: What They Are and How They Are Built · The AI Lecture Hall
© 2026 Janin A Apurba, CSE, AUST · Advanced ICT Officer, CNRS-UNHCR. All rights reserved. Notes for the animated lecture at https://ai-in-motion.vercel.app/watch/decoding-temperature-and-top-p.html