Data Augmentation for Vision — lecture notes
One image becomes many training examples: flips, rotations, crops, lighting changes and noise teach models what really matters.
0:001. Introduction
Labelled images are expensive. Data augmentation creates new training examples from the ones you already have, and it is one of the most effective tricks in computer vision.
0:122. Transformations
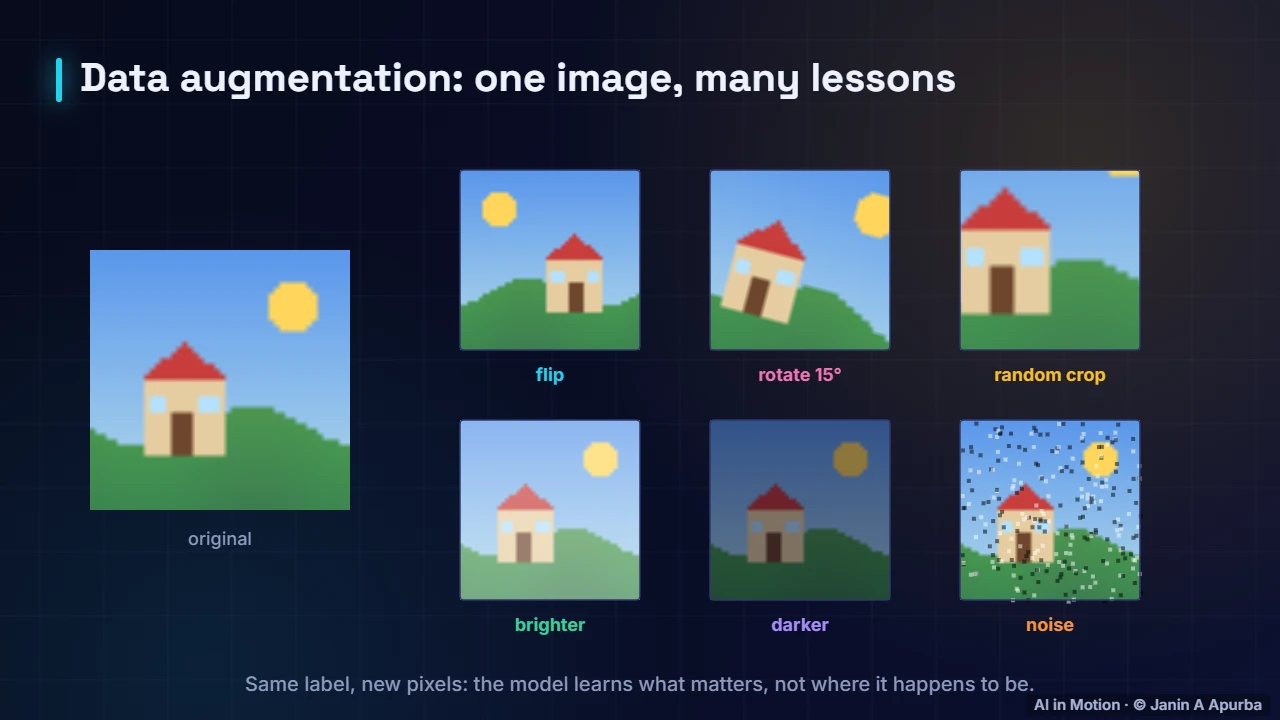
Take one image and transform it. Flip it horizontally. Rotate it slightly. Crop a random region. Make it brighter or darker. Add a little noise. The label stays the same: it is still a house. The model learns that these changes do not matter.
0:313. Why it works
Augmentation teaches invariance, the idea that a flipped or darker house is still a house. It makes memorising exact pixels harder, which reduces overfitting. And it simulates the variety of the real world.
0:454. Pitfalls
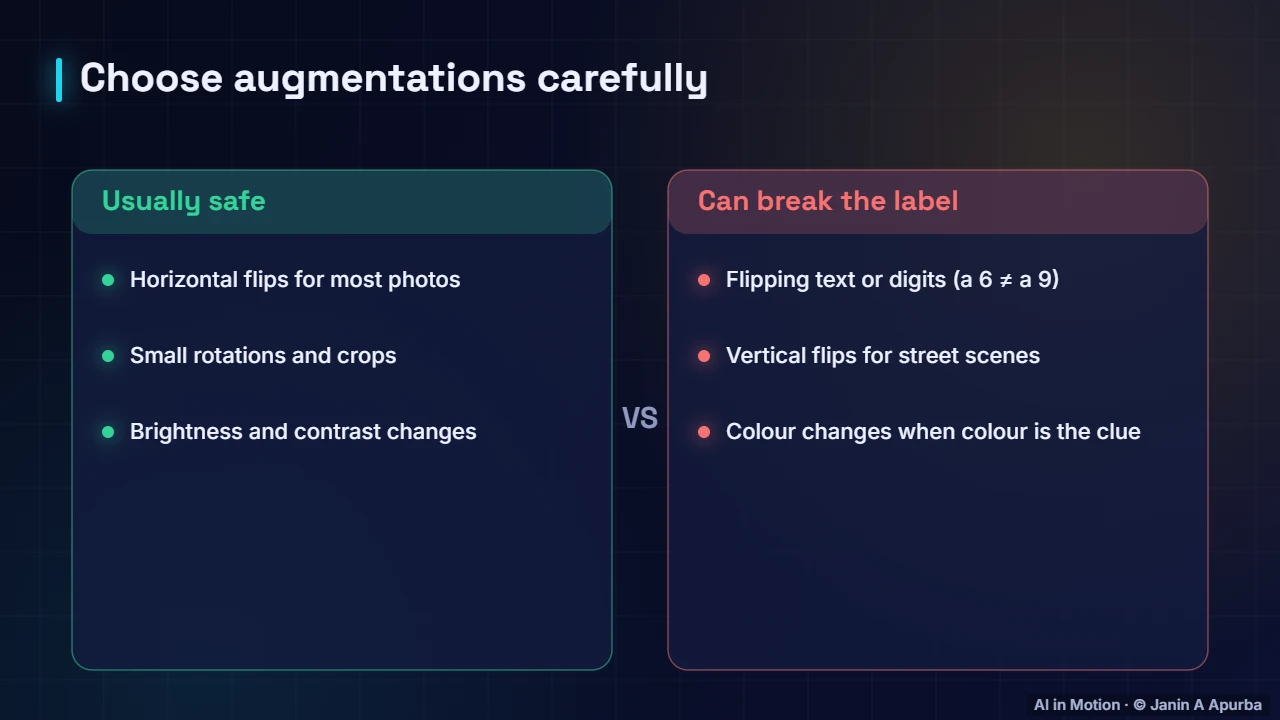
Choose augmentations that keep the label true. Horizontal flips suit most photos, but flipping text or digits can change their meaning. Colour changes are harmful if colour is the very thing you are classifying.
1:005. Advanced
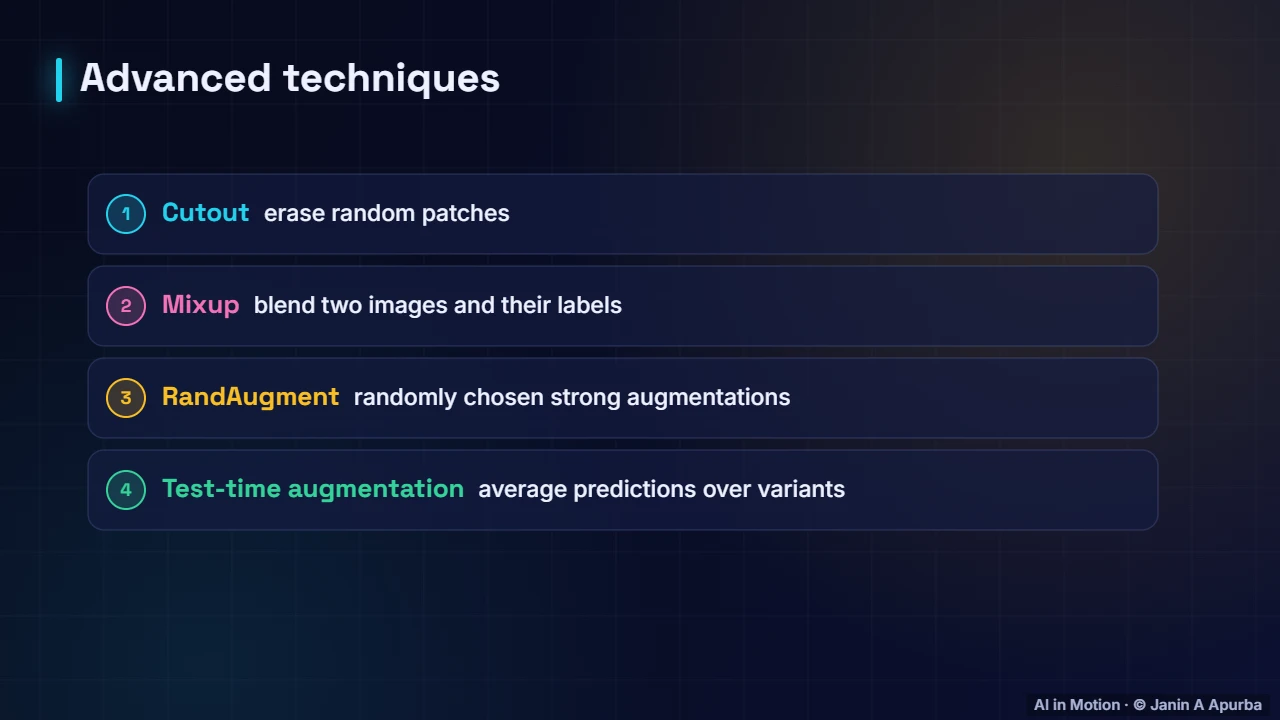
Advanced methods include cutout, which erases random patches, mixup, which blends two images and their labels, and RandAugment, which picks strong augmentations automatically.
1:116. Recap
To recap. Transform images but keep their labels. It teaches invariance and reduces overfitting. Pick transforms that keep the label true, and apply them on the fly during training.
Key takeaways
- Augmentation creates varied training images from existing ones.
- Flips, crops, rotations, lighting changes and noise are common.
- It teaches invariance and acts as regularisation.
- Only use transforms that keep the label correct.
Check yourself
- Why is flipping handwritten digits risky?
Show answer
It can change the meaning (e.g. confusing shapes) — Some transforms change what the label should be.
- Data augmentation mainly helps to…
Show answer
Reduce overfitting and teach invariance — Varied examples make memorisation harder.
- What does mixup do?
Show answer
Blends two images and their labels — Mixup trains on weighted blends of examples.
Go deeper
- Data Augmentation for Computer Vision · The AI Lecture Hall
- Regularisation in Deep Learning: Weight Decay, Early Stopping, Augmentation and More · The AI Lecture Hall
© 2026 Janin A Apurba, CSE, AUST · Advanced ICT Officer, CNRS-UNHCR. All rights reserved. Notes for the animated lecture at https://ai-in-motion.vercel.app/watch/data-augmentation.html